3 Supervised Learning, Prediction, and Evaluation
On this page
Supervised learning uses samples \((x_i,y_i)\) in a training set \(\Tset\), where both the feature vectors1Also called a vector of predictors, covariates, regressors, explanatory variables, or inputs. The precise name depends on the field and on whether the task is predictive or causal. \(x_i\) and the outcomes2Also called the target, response, label, dependent variable, or supervisory signal. \(y_i\) are observed, to learn a prediction rule \(f\). Once trained, we can use \(f\) to predict an outcome for a new3By new we mean an observation that was not used to fit the predictor. Its feature vector may equal one in the training set \(\Tset\). observed feature vector \(x\). Since the outcomes \(y_i\) are known for training, we call this supervised learning; the outcomes let us measure prediction errors made by \(f\) and use these errors to fit the rule.4We use rule, prediction function, and predictor interchangeably.
This chapter studies prediction rules, their losses, and the function classes from which we choose these rules. We consider regression and nominal classification, and find the best constant predictors and predictors based on affine functions for several losses. After these three prediction problems, we return to regression to study how nearest neighbors and polynomial degree control flexibility. We then discuss regularization, validation, and test data.
In the sequel we implicitly assume that all mathematical regularity conditions are satisfies, e.g. \(\E{X^2}\le \infty\), \(\E{f(X)^2} \le \infty\), and so on.
3.1 Prediction, loss and risk
We formulate supervised prediction as a statistical decision problem with four components: a random feature vector \(X\) is an element of the feature space \(\Xset\); an outcome \(Y\) lies in the outcome space \(\Yset\); a prediction function \(f\) maps feature vectors in \(\Xset\) to the prediction set \(\Aset\); and a loss function \(\lscr\). The set \(\Aset\) contains the objects our rule is allowed to output. In regression this is usually \(\R\); in classification it can be a set of labels, a vector of class scores, or a vector of class probabilities.
Sometimes the object returned by \(f\) is not itself the final label or value we report to the user. We then use a decision map
\begin{align*} d:\Aset\to\Yset, \qquad d(f(x))\in\Yset. \tag{3.1.1} \end{align*}For example, in classification \(f(x)\) may be a vector of class probabilities, while \(d(f(x))\) is the class with largest probability. To compare a prediction with an observed outcome, we use a label-lifting map
\begin{align*} r:\Yset\to\Aset \tag{3.1.2} \end{align*}that embeds \(y\) into the prediction set. We choose \(r\) so that \(d(r(y))=y\).5In general \(r(d(a))\neq a\): a hard label does not contain enough information to reconstruct a probability vector or score vector. In regression, usually \(\Aset=\Yset=\R\), and both \(d\) and \(r\) are the identity.
We use \(f(x)\) for the output of an arbitrary prediction rule, including a candidate Bayes predictor, and \(d(f(x))\) for its reported label or value. Hats indicate quantities computed from data, such as a fitted rule \(\hat f_{\Fset}\), fitted coefficients, or empirical risk \(\hat R_{\Tset}\).
Let the joint distribution of the random feature vector \(X\) and the related outcome \(Y\) be given by \(F_{X,Y}\). Typically \(F_{X,Y}\) is typically unknown, but it is conceptually useful as it can be imagined as the distribution from which the samples in the training set
\begin{align*} \Tset = [(x_1, y_1), \ldots, (x_n, y_n)] \end{align*}are drawn independently. We write \(x_i\) for a realized feature vector and \(y_i\) for a realized observed outcome. The \(j\)th feature coordinate of \(x\) is written as \(x(j)\). The pair \((x_i, y_i)\) is called a sample. We write \(\Tset\) as a list rather than a set because the same sample may occur more than once.6We will later see that bootstrap samples can contain the same sample multiple times. Thus \(n=|\Tset|\), and sums over \(\Tset\) count repeated entries separately. The order in \(\Tset\) itself has no meaning, but it allows us to refer unambiguously to the sample with index \(i\).
The assumption that the training samples and future samples come from the same distribution matters. If the population changes after fitting, then a predictor can perform poorly on new observations even when it did not overfit the training set. This problem is called distribution shift. Here we assume that the distribution function \(F_{X,Y}\) remains the same.
For a fixed prediction function \(f\), the population risk under the loss \(\lscr\)7The argument order matters: represented outcome first, prediction second. A loss need not be symmetric.
\begin{align*} R(f) = \E{\lscr(r(Y), f(X))} = \int \lscr(r(y), f(x)) \,\mathrm d F_{X,Y}(x,y). \tag{3.1.3} \end{align*}This is the expected loss on a new sample from the population. The Bayes optimal predictor for the chosen loss is
\begin{align*} f^{*} = \argmin_f R(f) = \argmin_f \E{\lscr(r(Y), f(X))} \tag{3.1.4} \end{align*}The value \(R(f^*)\) is called the Bayes risk. It is the smallest risk attainable for the prediction problem under the chosen loss, hence it is the irreducible risk that remains even for an optimal predictor.
If \(F_{X,Y}\) were known and the optimization over all prediction functions were feasible, the Bayes predictor would be the natural target. In practice we only have the training set \(\Tset\). To compute the training risk, we replace the integration in (3.1.3) over the (unknown) population distribution \(F\) with the probability measure induced8The probability measure is the normalized counting measure induced by \(\Tset\) and assigns each sample point a mass equal to the number of times it occurs. Dividing these masses by \(|\Tset|\) gives the empirical distribution. by \(\Tset\):9The subscript for an expectation indices the set over which to take the average.
\begin{align*} \hat R_{\Tset}(f) = \EE{\Tset}{\lscr(r(Y), f(X))} = \frac{1}{|\Tset|}\sum_{(x,y)\in\Tset} \lscr(r(y), f(x)). \end{align*}This leads to the optimization problem
\begin{align*} \argmin_f \hat R_{\Tset}(f). \end{align*}However, this unconstrained optimization problem10Minimizing training risk over all possible functions. is the wrong modeling problem. The result can fit the training samples perfectly while performing poorly on new samples. This is called overfitting. We want the predictor to generalize: it should also have low risk on new samples drawn from \(F_{X,Y}\).
To control overfitting we specify a model class \(\Fset\), a restricted set of prediction functions, and require that the fitted rule lies in \(\Fset\).11A model is just a function, but in machine learning the word model is often used for the fitted prediction rule together with its parametrization or construction method. The model class determines which rules can be fitted. A restrictive class allows only crude, but robust, fits; a large class may also contain functions that fit random variation in the training sample. Finding a good model space is an important part of the fitting process.
In this chapter we often consider the constant model class:
\begin{align*} \Fset_{\mathrm{const}}=\{f_c:c\in\Aset\},\qquad f_c(x)=c, \end{align*}that is, each rule returns the same prediction for every feature vector. The prediction \(c\) can be a numerical value or a probability vector, depending on the prediction set. For regression with numerical features \(x\in\Xset\subseteq\R^p\), we also consider the class of real-valued affine rules12\(\ip{\beta, x} = \sum_i \beta_i x_i\), i.e., the inner product.
\begin{align*} \Fset_{\mathrm{aff}} =\{\beta(\cdot):\beta(x)=\beta_0+\ip{\beta,x},\ \beta_0\in\R,\beta\in\R^p\}. \end{align*}The argument in \(\beta(x)\) distinguishes the affine function from its coefficient vector \(\beta\) in \(\ip{\beta,x}\). In regression, \(\Yset=\Aset=\R\), so the affine rule \(\beta(x)\) directly predicts the numerical outcome. In classification, \(\Yset\) contains class labels, while \(\Aset\) may contain probability vectors. We then use affine functions as scores and transform these scores into probability predictions in \(\Aset\). The decision map \(d\) converts a probability prediction into a class label in \(\Yset\). The probability predictions are generally not affine functions of \(x\).
In later chapters we discuss more flexible model classes, such as trees and neural networks.
The restriction of the optimization to \(\Fset\) gives two more prediction rules besides the Bayes predictor:
\begin{align*} f_{\Fset}^{*} &= \argmin_{f\in \Fset} R(f), & \hat f_{\Fset} &= \argmin_{f\in \Fset} \hat R_{\Tset}(f). \tag{3.1.5} \end{align*}The function \(f_{\Fset}^{*}\) is the best-in-class predictor: it is the best rule in \(\Fset\) for the true population risk. The function \(\hat f_{\Fset}\) is the empirical risk minimizer: it is the rule in \(\Fset\) with the smallest training risk. In both predictors, the subscript \(\Fset\) identifies the model class over which we optimize. The star indicates minimization of population risk \(R\); the hat indicates minimization of empirical risk \(\hat R_{\Tset}\), computed using the probability measure induced by \(\Tset\). The fitted rule \(\hat f_{\Fset}\) depends on \(\Tset\), but we leave this dependence implicit unless we need to distinguish fits on different training lists.
Since \(f_{\Fset}^{*}\) optimizes only over \(\Fset\), while the Bayes predictor optimizes over all prediction functions, we have that the approximation error
\begin{align*} R(f_{\Fset}^{*}) - R(f^{*}) \ge 0. \tag{3.1.6} \end{align*}The approximation error is the increase in risk caused by restricting the optimization to the model class \(\Fset\). If \(\Fset\) is too small, even the best rule in the class cannot achieve a risk close to the Bayes risk. The estimation error
\begin{align*} R(\hat f_{\Fset}) - R(f_{\Fset}^{*}) \ge 0 \tag{3.1.7} \end{align*}results from choosing a rule that optimizes \(\hat R_{\Tset}\) (over a model class) rather than \(R\).13These rules generally differ: one minimizes population risk, the other training risk over the same model class \(\Fset\).
The risks combined give the standard decomposition of the excess risk:
\begin{align*} R(\hat f_{\Fset}) - R(f^{*}) &= \underbrace{R(\hat f_{\Fset}) - R(f_{\Fset}^{*})}_{\text{estimation error}} + \underbrace{R(f_{\Fset}^{*}) - R(f^{*})}_{\text{approximation error}}. \tag{3.1.8} \end{align*}This decomposition explains a tradeoff in model choice. Enlarging \(\Fset\) can reduce the approximation error, because we minimize risk over more functions. But a larger class can also increase the estimation error, because the empirical risk minimizer can adapt more strongly to random noise in \(\Tset\). The subtle point is that the training risk \(\hat R_{\Tset}(\hat f_{\Fset})\) cannot increase when \(\Fset\) is enlarged, but the population risk \(R(\hat f_{\Fset})\) can.
Many texts discuss this tradeoff in terms of bias and variance. The usual bias-variance decomposition is a squared-loss identity that averages over possible training samples. It separates risk in a different way from the approximation/estimation decomposition above. We derive it when we specialize to squared loss below.
The next three sections apply the above definitions to regression, nominal classification, and ordinal prediction.
3.2 Regression
Regression problems aim to predict numerical values such as a price, a travel time, or a demand level.14Wikipedia: Regression analysis. Therefore, in a regression problem, \(\Yset=\Aset=\R\), and the decision map \(d\) and label-lifting map \(r\) are identity maps.15In classification problems, this is no longer the case. For a prediction function \(f:\Xset\to\R\), the prediction error on a case is
\begin{align*} Y-f(X).. \end{align*}The squared loss and absolute loss below are a function of this error. For each loss, we first derive the Bayes predictor, then find the best predictors within the constant and affine model classes. Replacing population risk by training risk gives practical fitting procedures: squared loss leads to the sample mean and ordinary least squares, while absolute loss leads to sample medians and least absolute deviations regression.
3.2.1 Squared loss
The most common loss for regression is squared loss,
\begin{align*} \lscr(y,f(x)) &= \frac{1}{2}(y-f(x))^2, & \lscr \in [0,\infty). \end{align*}Clearly, this loss penalizes large prediction errors because then \((Y-f(X))^2\) is large. Likelihood maximization offers another view. Suppose, as an approximation, that conditional on the feature vectors, the labels \(Y_i\) are independent normal random variables with means \(f(X_i)\) and common variance \(v>0\):
\begin{align*} Y_i \mid X_i \sim \Norm{f(X_i),v}. \end{align*}Then the likelihood of the observed labels in \(\Tset\) is
\begin{align*} L(f,v) &= \prod_{(x,y)\in\Tset} \frac{1}{\sqrt{2\pi v}} \exp\rb{-\frac{(y-f(x))^2}{2v}}. \end{align*}Taking the negative logarithm16Unless a base is shown explicitly, \(\log\) means the natural logarithm throughout these notes. to convert the product into a sum gives
\begin{align*} -\log L(f,v) &= \frac{n}{2}\log(2\pi v) + \frac{1}{2v}\sum_{(x,y)\in\Tset} (y-f(x))^2. \end{align*}For fixed \(v>0\), maximizing the likelihood over \(f\) is therefore the same as minimizing the empirical squared loss.
To find the optimal rule for square loss, suppose we know \(F_{X,Y}\) and may choose any prediction function. As a first step, we decompose the risk in a way that will be useful throughout this section. It separates the part of the error that can be reduced by choosing a better prediction rule from the variation in \(Y\) that remains once \(X\) is known.
Theorem 3.2.1.
Let \(m(X) = \E{Y \mid X}\) be the conditional expectation of \(Y\) given \(X\). Then, for every \(f:\Xset\to\R\),
\begin{align*} R(f)=\frac{1}{2}\E{(Y-f(X))^{2}} &= \underbrace{\frac{1}{2}\E{\rb{m(X)-f(X)}^{2}}}_{\text{excess risk of \(f\)}} + \underbrace{\frac{1}{2}\E{\V{Y|X}}}_{\text{irreducible risk}}. \tag{3.2.1} \end{align*}Proof
Write the prediction error \(Y-f(X)\) as \((Y-m(X))+(m(X)-f(X))\):
\begin{align*} \frac{1}{2}\E{(Y-f(X))^{2}} &= \frac{1}{2}\E{\rb{\rb{Y-m(X)} + \rb{m(X)-f(X)}}^{2}} \\ &= \frac{1}{2}\E{\rb{m(X)-f(X)}^{2}} + \E{\rb{m(X)-f(X)}\rb{Y-m(X)}}\\ &\quad + \frac{1}{2}\E{\rb{Y-m(X)}^{2}}. \end{align*}By conditioning on \(X\) in the middle term,
\begin{align*} \E{\rb{m(X)-f(X)}\rb{Y-m(X)} \given X} = \rb{m(X)-f(X)} \E{Y-m(X) \given X}= 0, \end{align*}because \(m(X) = \E{Y \given X}\).
With respect to the third term, conditioning on \(X\) yields
\begin{align*} \E{\rb{Y-m(X)}^{2}\given X} &= \E{Y^{2}\given X} - 2m(X)\E{Y\given X} + m(X)^{2}\\ &= \E{Y^{2}\given X} - m(X)^{2} &= \V{Y\mid X}. \end{align*}The last equation follows from the definition of conditional variance
\begin{align*} \V{Y\mid X} &= \E{(Y-\E{Y\mid X})^{2}\mid X} = \E{Y^{2}\mid X} - m(X)^{2}. \end{align*}Taking expectations completes the proof.
The Bayes regressor17That is, the Bayes optimal predictor (3.1.4) for a regression problem. under squared loss now follows easily.
Corollary 3.2.2.
When \(f\neq m\), \(\E{(f(X) - m(x))^2} \geq 0\). Hence, \(R(f) \geq R(m)\) for any \(f\). Consequently, the conditional expectation \(f^{*}(x) = m(x) = \E{Y \mid X=x}\) attains the Bayes risk \(R(f^{*}) = R(m) = \frac{1}{2}\E{\V{Y\mid X}}\). Next, from Eve’s law18Eve’s law, also known as the law of total variance, states that \(\V Y = \E{\V{Y\mid X}} + \V{\E{Y\mid X}}\). it is immediate that \(R(f^{*}) \leq \frac{1}{2}\V Y\).
Fitting the best constant function requires minimizing \(\frac{1}{2}\E{(m(X) -c)^2}\) in (3.2.1). Expanding the square and using that \(\E{m(X)} = \E Y\), gives
\begin{align*} \frac{1}{2}\E{m(X)^{2}} +\frac{1}{2}c (c-2 \E Y). \end{align*}This is minimal at \(c^* = \E Y\), and then the risk \(R(c^*)\) becomes
\begin{align*} c^{*} &= \E Y, & R(c^*) &= \frac{1}{2}\E{\V{Y\mid X}} + \frac{1}{2}\E{m(X)^{2}} - \frac{1}{2}(\E Y)^{2} = \frac{1}{2}\V Y, \tag{3.2.2} \end{align*}where the last step follows from Eve’s law.
To obtain the empirical risk minimizer and minimal empirical risk, we replace \(F_{X,Y}\) by the probability measure induced by \(\Tset\) to get
\begin{align*} \hat c &= \frac{1}{|\Tset|}\sum_{(x,y)\in\Tset}y, & \hat R_{\Tset}(\hat c) &= \frac{1}{2|\Tset|}\sum_{(x,y)\in\Tset}(y-\hat c)^2. \tag{3.2.3} \end{align*}Fitting an affine prediction rule minimizes the excess-risk term in (3.2.1):
\begin{align*} \frac{1}{2}\E{\rb{m(X)-\beta(X)}^2}. \end{align*}Setting the partial derivatives wrt \(\beta\) and \(\beta_0\) to zero gives the population normal equations:
\begin{align*} \beta(\E{X}) &= \E Y,\\ \E{\rb{m(X)-\beta(X)}X(j)} &= 0, \qquad j=1,\ldots,p. \end{align*}Replacing \(F_{X,Y}\) by the normalized counting measure induced by \(\Tset\) and writing \(\hat\beta(x)=\hat\beta_0+\ip{\hat\beta,x}\) for the fitted rule gives
\begin{align*} \hat\beta(\hat x) &= \sum_{(x,y)\in \Tset} y, \\ \sum_{(x,y)\in\Tset}\rb{y-\hat\beta(x)}x(j) &= 0, \qquad j=1,\ldots,p. \end{align*}These solve the ordinary least squares (OLS) problem:
\begin{align*} (\hat\beta_0,\hat\beta) &=\argmin_{\beta_0,\beta}\hat R_{\Tset}(\beta(\cdot)), \tag{3.2.4} \\ \hat R_{\Tset}(\beta(\cdot)) &=\frac{1}{2|\Tset|}\sum_{(x,y)\in\Tset} \rb{y-\beta(x)}^2. \tag{3.2.5} \end{align*}Restricting the affine class to \(\beta=0\) recovers the constant class: the population equation gives \(\beta_0^*=\E{Y}\) and the sample equation gives \(\hat\beta_0=\hat c\) of (3.2.3).
Bias and variance are two forms of error that appear through the approximation of the Bayes predictor \(m\) by the empirical risk minimizer \(\hat f_{\Fset}\), (3.1.5). There are two sources of randomness to distinguish. The training set \(\Tset\) can itself be seen as a list of iid samples from \(F_{X,Y}\). Once \(\Tset\) is known and the rule \(\hat f_{\Fset}\) is fitted, a new observation \((X,Y)\), independent of \(\Tset\) and also with distribution \(F_{X,Y}\), offers the second source of randomness. Let us fix \(X =x\) first, and concentrate on the effect of the randomnes s of \(\Tset\). Write19A subscript on an expectation indicates which random variable is averaged over; a vertical bar indicates conditioning.
\begin{equation*} \bar f(x)=\EE{\Tset}{\hat f_{\Fset}(x)} \tag{3.2.6} \end{equation*}for the average prediction at \(x\) over the iid training sets. The bias \[ \bar f(x)-m(x) \] is the systematic discrepancy between the average fitted prediction and the conditional mean.20Recall from Cor. 3.2.2 that \(m(x)\) is precisely the Bayes regressor. The variance
\begin{align*} \EE{\Tset}{\rb{\bar f(x) - \hat f_{\Fset}(x)}^{2}} \end{align*}measures how the fitted prediction changes when we draw a new training sample.
Theorem 3.2.3.
The average risk of the empirical risk minimizer can be decomposed as:21The expectation on the left is over training sets; the outer expectations on the right are over \(X\).
\begin{align*} \EE{\Tset}{R(\hat f_{\Fset})} &=\underbrace{\frac{1}{2}\EE{X}{\V{Y\mid X}}}_{\text{irreducible risk}} +\underbrace{\frac{1}{2}\EE{X}{\rb{\bar f(X)-m(X)}^{2}}}_{\text{squared bias}} +\underbrace{\frac{1}{2}\EE{X}{\V{\hat f_{\Fset}(X)\mid X}}}_{\text{variance}}. \tag{3.2.7} \end{align*}Proof
We use (3.2.1). Conditional on \(\Tset\), the fitted rule is fixed, so that decomposition gives
\begin{align*} R(\hat f_{\Fset}) &= \frac{1}{2}\EE{X}{\V{Y\mid X}} + \frac{1}{2}\EE{X}{(m(X)-\hat f_{\Fset}(X))^2\mid\Tset}. \end{align*}Averaging over training sets and exchanging the expectations in the second term yields
\begin{align*} \EE{\Tset}{R(\hat f_{\Fset})} &= \frac{1}{2}\EE{X}{\V{Y\mid X}} + \frac{1}{2}\EE{X}{\EE{\Tset}{(m(X)-\hat f_{\Fset}(X))^2\mid X}}. \end{align*}Note that the exchange \(\EE{\Tset}{\EE{X}{\cdot}}\) to \(\EE{X}{\EE{\Tset}{\cdot}}\) is valid by independence and Tonelli’s theorem, since the squared deviation is nonnegative.
For fixed \(X\), expand the second term around \(\bar f(X)=\EE{\Tset}{\hat f_{\Fset}(X)\mid X}\):
\begin{align*} m(X)-\hat f_{\Fset}(X) &= (m(X)-\bar f(X))+(\bar f(X)-\hat f_{\Fset}(X)). \end{align*}Squaring and taking the conditional expectation given \(X\) gives
\begin{align*} \EE{\Tset}{(m(X)-\hat f_{\Fset}(X))^2\mid X} &= (m(X)-\bar f(X))^2 \\ &\quad +2(m(X)-\bar f(X)) \EE{\Tset}{\bar f(X)-\hat f_{\Fset}(X)\mid X} \\ &\quad +\EE{\Tset}{(\bar f(X)-\hat f_{\Fset}(X))^2\mid X}. \end{align*}Here \(m(X)\) and \(\bar f(X)\) are fixed conditional on \(X\). The cross term vanishes because
\begin{align*} \EE{\Tset}{\bar f(X)-\hat f_{\Fset}(X)\mid X} &= \bar f(X)-\EE{\Tset}{\hat f_{\Fset}(X)\mid X}=0. \end{align*}The last term is the conditional variance of the fitted prediction, so
\begin{align*} \EE{\Tset}{(m(X)-\hat f_{\Fset}(X))^2\mid X} &= (m(X)-\bar f(X))^2 + \V{\hat f_{\Fset}(X)\mid X}. \end{align*}Substituting this identity into the expression for \(\EE{\Tset}{R(\hat f_{\Fset})}\) above gives the claimed decomposition.
Feature selection affects both bias and variance. Suppose for this paragraph that the feature coordinates are uncorrelated, so that leaving one out does not disturb the estimates of the others. A feature with \(\beta_{j}=0\) has no contribution to the conditional mean, so estimating its coefficient adds variance without reducing bias. Omitting it therefore lowers the variance of the fitted rule without increasing bias. On the other hand, when we leave out a feature with \(\beta_{j}\neq0\) its contribution \(\beta_{j}x(j)\) to the residual
\begin{align*} y-\hat\beta_0-\sum_{k\neq j}\hat\beta_k x(k) \end{align*}must be picked up by the other factors. This introduces bias and raises the variance of the remaining estimates.
Feature selection aims to retain useful features and omit the ones that add only estimation noise. The lasso in Section 3.5 is one method for selecting relevant features.
3.2.2 Absolute loss
An alternative loss to squared loss is the absolute loss
\begin{align*} \lscr(y,f(x)) &= |y-f(x)|, & \lscr \in [0,\infty). \tag{3.2.8} \end{align*}It is less sensitive to outliers than squared loss because it grows linearly with the magnitude of the error. Its Bayes regressor is the conditional median, as the following definition and theorem show.
Definition 3.2.4.
A median \(\med{Y}\) of a random variable \(Y\) is a number \(m\) such that
\begin{align*} \P{Y\leq m}\geq 1/2 \qquad\text{and}\qquad \P{Y\geq m}\geq 1/2. \end{align*}A conditional median \(\med{Y\mid X=x}\) is any median of the conditional distribution of \(Y\) given \(X=x\); that is, any number \(m(x)\) such that
\begin{align*} \P{Y\leq m(x)\given X=x}\geq 1/2 \qquad\text{and}\qquad \P{Y\geq m(x)\given X=x}\geq 1/2. \end{align*}To see why medians arise, consider the slopes of the graphs in Fig. 3.1--Fig. 3.4. Viewed as a function of \(c\), a term \(|y-c|\) has slope \(+1\) when \(y<c\) and slope \(-1\) when \(y>c\). Thus, to get the slope of the sum of such functions, when \(c\) is not equal to any of the \(y\), we can just count the number of labels \(y\) lying to the left and the right of \(c\). When changing \(c\) a tiny bit, all terms \(|y-c|\) with \(y>c\) contribute \(-1\) to the slope of the sum, and the ones with \(y<c\) contribute \(+1\). Clearly, any such sum is convex. When the number of labels is odd, the minimum of the sum is achieved at the median; otherwise it is flat between the two middle labels. For instance, for the two labels 1 and 3, the sum is constant between the two labels, so every \(c\in[1,3]\) is a minimizer. After adding the middle label 2, the sum has its unique minimum at \(c=2\).
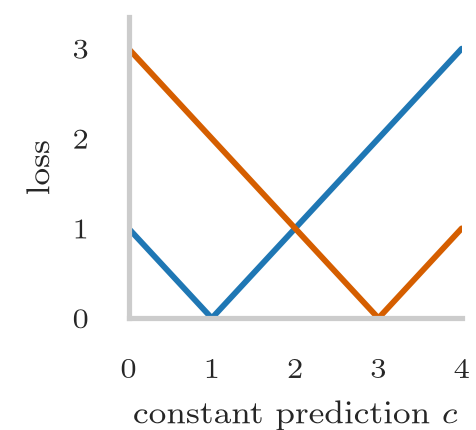
Figure 3.1: The plots of \(|y_1-c|\) and \(|y_2-c|\), with \(y_1=1\) and \(y_2=3\).
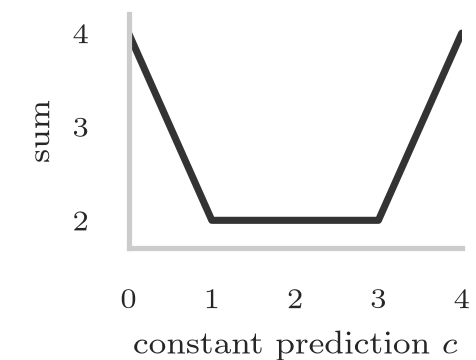
Figure 3.2: The plot of \(|y_1-c|+|y_2-c|\), with \(y_1=1\) and \(y_2=3\).
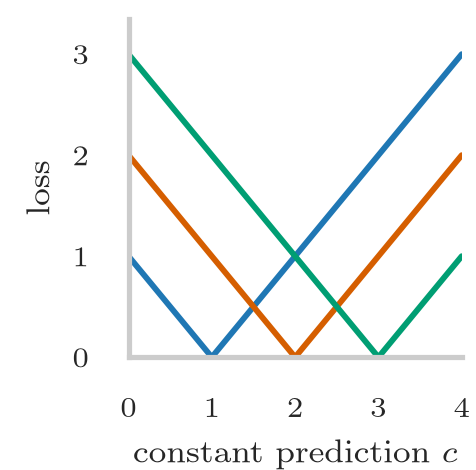
Figure 3.3: The plots of \(|y_i-c|\), with \(y_1=1\), \(y_2=2\), and \(y_3=3\).
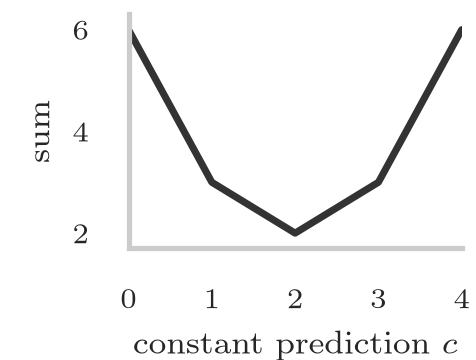
Figure 3.4: The plot of \(\sum_{i=1}^3|y_i-c|\), with \(y_1=1\), \(y_2=2\), and \(y_3=3\).
Let us apply this idea to understand the empirical risk of the constant prediction \(f(x)=c\) for a list of observations \(\Sset\):
\begin{align*} \hat R_{\Sset}(c)=\frac{1}{|\Sset|} \sum_{(x,y)\in\Sset}|y-c|. \end{align*}Define
\begin{align*} \Lset(c)&=\{(x,y)\in\Sset:y\leq c\}, & \Rset(c)&=\Sset\setminus\Lset(c)=\{(x,y)\in\Sset:y>c\}. \end{align*}It follows that for \(c\notin\set{y:(x,y)\in\Sset}\),
\begin{align*} \hat R'_{\Sset}(c) &=\frac{|\Lset(c)|-|\Rset(c)|}{|\Sset|} =2\frac{|\Lset(c)|}{|\Sset|}-1. \end{align*}To specify this derivative everywhere on \(\R\), define it at \(c=y\) as22It becomes a right-continuous function with this.
\begin{align*} \hat R'_{\Sset}(y) := \hat R'_{\Sset}(y+) = \lim_{c\downarrow y}\hat R'_{\Sset}(c). \end{align*}The empirical risk is convex, so it is minimized where its derivative changes from negative to positive, possibly through an interval on which it is zero. At any such point at most half the labels lie strictly below a minimizer and at most half lie strictly above it: these are exactly the sample-median conditions.
The same counting argument, now applied to the conditional distribution of \(Y\) given \(X=x\), gives the Bayes predictor.
Theorem 3.2.5.
A minimizer of \(R(f)=\E{\lscr(Y,f(X))} = \E{\abs{Y-f(X)}}\) over all prediction rules in (3.1.4) is given by the conditional median
\begin{align*} f^{*}(X) &= \med{Y \mid X} & f^{*}(x) = \med{Y \mid X=x}. \end{align*}Proof
Conditioning on \(X\) gives \(R(f)=\E{\,\E{\abs{Y-f(X)}\given X}}\). Given \(X=x\), the prediction is the constant \(c=f(x)\), so we minimize \(\E{\abs{Y-c}\given X=x}\) over \(c\). Imagine increasingly large lists \(\Sset_n\) whose labels are sampled independently from the conditional distribution of \(Y\) given \(X=x\). By the law of large numbers,23We omit the technical details needed to justify this passage to the limit. the empirical proportion \(|\Lset_n(c)|/|\Sset_n|\) converges to \(\P{Y\leq c\given X=x}\). Consequently, the empirical right slope \(2|\Lset_n(c)|/|\Sset_n|-1\) converges to \(2\P{Y\leq c\given X=x}-1\). The left limit of this limiting slope is \(2\P{Y<c\given X=x}-1\).
The conditional risk \(\E{|Y-c|\mid X}\) is convex and coercive,24A function \(f\) is coercive if \(f(x)\to\infty\) when \(|x|\to\infty\). so it has a minimizer \(m\). At this minimizer,
\begin{align*} 2\P{Y<m\given X=x}-1 \leq 0 \leq 2\P{Y\leq m\given X=x}-1, \end{align*}hence at \(m\),
\begin{align*} \P{Y<m\given X=x} \leq \frac 1 2 \leq \P{Y\leq m\given X=x}. \end{align*}Thus, \(m\) satisfies the definition of the median; \(m=\med{Y\mid X=x}\). Choosing such a conditional median \(m(x)\) for for each \(x\) minimizes \(R(f)\).
Constant functions as predictors have the form \(f(x)=c\), \(c\in\R\). The population and empirical calculations above immediately give
\begin{align*} R(c)&=\E{\abs{Y-c}}, & c^*&=\med{Y}, \end{align*}and the empirical risk minimizer is
\begin{align*} \hat m&=\med{y:(x,y)\in\Tset}, & \hat m&=\argmin_{c\in\R}\hat R_{\Tset}(c). \tag{3.2.9} \end{align*}The attained cost has a simple form. Use the same three-way partition as Quicksort Alg. 2.3.2 with the median \(\hat m\) as the pivot:25A median label is an optimal pivot for balancing Quicksort’s recursive subproblems: both \(\Lset\) and \(\Rset\) contain at most half the observations.
\begin{align*} \Lset&=\set{(x,y)\in\Tset:y<\hat m},& \Mset&=\set{(x,y)\in\Tset:y=\hat m},& \Rset&=\set{(x,y)\in\Tset:y>\hat m}. \end{align*}The observations in \(\Mset\) contribute zero to the absolute loss. Resolving the remaining absolute values gives
\begin{align*} \hat R_{\Tset}(\hat m) &=\frac{1}{|\Tset|}\sum_{(x,y)\in\Tset}\abs{y-\hat m}\\ &=\frac{1}{|\Tset|}\sum_{(x,y)\in\Lset}\rb{\hat m-y} +\frac{1}{|\Tset|}\sum_{(x,y)\in\Rset}\rb{y-\hat m}\\ &=\frac{1}{|\Tset|}\rb{ \sum_{(x,y)\in\Rset}y-\sum_{(x,y)\in\Lset}y +\hat m\rb{|\Lset|-|\Rset|}}. \end{align*}If \(|\Lset|=|\Rset|\), the contributions involving \(\hat m\) cancel.
For affine functions as predictors the best-in-class predictor is not informative. However, the median regression
\begin{align*} \begin{split} (\hat\beta_0,\hat\beta) &=\argmin_{\beta_0,\beta}\hat R_{\Tset}(\beta(\cdot)),\\ \hat R_{\Tset}(\beta(\cdot)) &=\frac{1}{|\Tset|}\sum_{(x,y)\in\Tset}\abs{y-\beta(x)} \end{split} \tag{3.2.10} \end{align*}can be solved as an interesting linear program:
\begin{align*} \min_{\beta_0,\beta,t}\quad &\frac{1}{|\Tset|}\sum_{i=1}^{|\Tset|}t_i\\ \text{subject to}\quad &-t_i\le y_i-\beta(x_i)\le t_i,& i=1,\ldots,|\Tset|, \\ &t_i\ge 0,& i=1,\ldots,|\Tset|. \end{align*}At an optimum, \(t_i\) equals the absolute residual, so the objective is precisely (3.2.10).
Note that restricting to \(\beta=0\) recovers the marginal median at population level.
3.3 Nominal classification
Nominal classification26Also called categorical classification. problems have categorical labels without a natural order, for instance, classifying photos with cats and dogs. This means that for \(K\)-class nominal classification, the label lies in the class index set27It is common to assume that labels like colors, animals, \ldots, are converted to numbers.
\begin{align*} \Yset &= \Kset = \set{0, 1}, \\ \Yset&=\Kset = \set{1, \ldots, K}, \quad K = 3, 4, \ldots \end{align*}Throughout this section the prediction set is \(\Aset = \Delta_{K}\), where the probability simplex
\begin{align*} \Delta_K=\set{u\in\R^K:u_k\geq0\text{ for all }k\in\Kset,\ \sum_{k\in\Kset}u_k=1}. \end{align*}A probability prediction is a rule \(f: \Xset \to \Delta_K\) so that \(f_k(x)\) is the predicted probability of class \(k\). The decision map is the majority vote,
\begin{align*} d: \Delta_{K} &\to \Kset, & d(p)&=\argmax_{k\in\Kset} p_k. \tag{3.3.1} \end{align*}In the other direction, the one-hot encoding lifts the observed class \(y\) to a probability vector by putting all probability on the observed class and zero on all others:
\begin{align*} r: \Kset &\to \Delta_{k}, & r_k(y)&=\1{y=k}. \end{align*}Consequently,
\begin{equation*} d(r(y)) = \argmax_{k\in \Kset} r_{k}(y) = \argmax_{k\in \Kset} \1{y =k} = y. \tag{3.3.2} \end{equation*}Write \(p\) and \(p(x)\) for the vectors with components28the marginal and conditional probabilities.
\begin{align*} p_{k} &= \P{Y=k} = F_{X,Y}(\infty, k), & p_{k}(x) &= \P{Y=k \mid X=x} = F_{Y\mid X}(k\mid x), \end{align*}where we assume that the joint distribution \(F_{X,Y}\) is known.29At least conceptually.
For any list \(\Sset\) whose labels lie in \(\Kset\), \(\Sset_{k} = \qb{(x,y)\in\Sset : y=k}\) is the sublist of samples of class \(k\). In particular, for the training list \(\Tset\), write \(\Tset_k=\qb{(x,y)\in\Tset:y=k}\) and \(\hat p_k=|\Tset_k|/|\Tset|\). The vector \(\hat p=(\hat p_k)_{k\in\Kset}\) contains the empirical class frequencies.
We study four loss functions for nominal classification: zero-one loss, Brier loss, cross-entropy loss, and absolute loss. As in regression, we examine the Bayes predictors and the best constant predictors, then replace population risk by training risk to obtain practical fitting procedures. We will see that zero-one loss is useful for evaluating classification accuracy, but less suitable for fitting probability predictions. Absolute loss on one-hot vectors also fails to recover the true class probabilities in general. The expected Brier and cross-entropy losses are minimized at the true probability vector. A loss with that property is called a proper scoring rule.30Wikipedia: Scoring rule. We will use both losses extensively later. Finally, fitting affine scores with cross-entropy loss leads to logistic regression.31For binary classification, this is a the simplest possible neural network: it consists of a single sigmoid output neuron with no hidden layers.
3.3.1 Zero-one loss
Zero-one loss compares samples based on class. Using (3.3.2),
\begin{align*} \lscr(r(y),f(x)) &= \1{y \neq d(f(x))} = \1{y \neq \argmax_{k\in\Kset}f_k(x)}, & \lscr \in \set{0,1}. \tag{3.3.3} \end{align*}The next numerical example shows an important problem with zero-one loss. Take \(\Kset=\set{0,1}\) and an observed class \(y=1\), so that \(r(y)=r(1) = (0,1)\). Compare the probability predictions where the first is hesitant, the other confident:
\begin{align*} p^{A}&=(0.49,0.51), & p^{B}&=(0.01,0.99). \end{align*}Both have maximizing class \(1\), since \(p_1^{A}>p_0^{A}\) and \(p_1^{B}>p_0^{B}\). Using (3.3.3),
\begin{align*} \lscr(r(1),p^{A}) &=\1{1\neq\argmax_{k\in\Kset}p_k^{A}}=\1{1\neq1}=0,\\ \lscr(r(1),p^{B}) &=\1{1\neq\argmax_{k\in\Kset}p_k^{B}}=\1{1\neq1}=0. \end{align*}Thus zero-one loss gives the same value to a hesitant prediction and a confident prediction. Optimizing under this loss is difficult because small changes in the probabilities often leave the predicted label unchanged.
For any rule \(f:\Xset\to\Delta_K\), using (3.3.3) gives the conditional risk
\begin{align*} \E{\lscr(r(Y),f(X))\mid X} &= \E{\1{Y \neq \argmax_{k\in\Kset}f_k(X)}\mid X} \\ &= \P{Y \neq \argmax_{k\in\Kset}f_k(X)\mid X} \\ &= 1 - \P{Y = \argmax_{k\in\Kset}f_k(X)\mid X}. \end{align*}Now take \(f(x) = p(x)\) with components
\begin{align*} f^{*}_{k}(x) = \P{Y=k \mid X=x} = p_{k}(x). \tag{3.3.4} \end{align*}Then the expected loss is minimized when the predicted class is the most probable because
\begin{align*} \P{Y = \argmax_{k\in\Kset}f_k(X)\mid X} = \argmax_{k\in\Kset}\P{Y=k\mid X}. \end{align*}Thus, \(f\) can serve as a Bayes predictor.
A constant predictor maps, via the decision map \(d\), any \(x\in \Xset\) to some constant \(k\in \Kset\). With this, the risk is easy:
\begin{align*} R(k) = \E{Y\neq k} = 1-\P{Y=k}. \end{align*}Thus the best constant predictor is the majority class and the risk is the misclassification rate,
\begin{align*} c^{*} &= \argmax_{k} |\Tset_{k}|, & \hat R_{\Tset}(c^{*}) &= 1 - \max_{k} \hat p_{k}. \tag{3.3.5} \end{align*}3.3.2 Brier loss
The Brier loss32Wikipedia: Brier score.
\begin{align*} \lscr(r(y),f(x)) &= \sum_{k\in\Kset}(r_k(y)-f_k(x))^2, & \lscr \in [0,2], \tag{3.3.6} \end{align*}compares the one-hot representation \(r(y)\) to the prediction \(f(x)\).
A numerical example shows the advantage of Brier loss over zero-one loss. For the example in zero loss,33\(\Kset=\set{0,1}\), observed class \(y=1\), \(p^{A} = (0.49,0.51)\), \(p^{B} = (0.01,0.99)\). the Brier loss becomess \(p^{A}\),
\begin{align*} \lscr(r(1),p^{A}) &= (r_0(1)-p^{A}_{0})^{2} + (r_1(1)-p^{A}_{1})^{2} \\ &= (0-0.49)^2 + (1-0.51)^2 \\ &\approx 0.48. \\ \lscr(r(1),p^{B}) &= (0-p^{B}_{0})^{2} + (1-p^{B}_{1})^{2} \\ &= (0-0.01)^2 + (1-0.99)^2 \\ &= 0.0002. \end{align*}Thus the second prediction receives a much smaller Brier loss.
For the Bayes predictor we split the risk in a similar way as Th. 3.2.1. As the \(k\)th component of \(r(Y)\) is \(\1{Y=k}\), the Brier loss becomes
\begin{align*} \E{\lscr(r(Y), f(X))} = \E{\sum_{k\in\Kset}\rb{\1{Y=k} - f_{k}(X)}^{2}} = \sum_{k\in\Kset} \E{\rb{\1{Y=k} - f_{k}(X)}^{2}}. \end{align*}To minimize this, as \(f_k(X)\) is free, it suffices to minimize each terms separately. But observe that \(\E{\rb{\1{Y=k} - f_{k}(X)}^{2}}\) is a regression problem under square loss. We can therefore directly use the formulas of Th. 3.2.1 with \(\1{Y=k}\) in the role of \(Y\) and \(f_k(X)\) in the role of \(f(X)\). Thus, 34Recalll \(\E{\1{X}} = p\) \(\implies\) \(\V{\1{X}} = p(1-p)\).
\begin{align*} \E{\1{Y=k}\mid X} &= p_{k}(X), & \V{\1{Y=k}\given X} &= p_{k}(X)\rb{1-p_{k}(X)}. \end{align*}Summing the variances over \(k\) and using that the \(p_{k}(x)\) add up to one,
\begin{align*} \sum_{k\in\Kset} p_{k}(x)\rb{1-p_{k}(x)} = 1 - \sum_{k\in\Kset} p_{k}(x)^{2}. \end{align*}Therefore, immediately from Th. 3.2.1:
Theorem 3.3.1.
For every \(f:\Xset\to\Delta_K\),
\begin{align*} R(f)=\E{\lscr(r(Y), f(X))} &= \underbrace{\E{\sum_{k\in\Kset}\rb{f_{k}(X)-p_{k}(X)}^{2}}}_{\text{squared error}} + \underbrace{\E{1 - \sum_{k\in\Kset} p_{k}(X)^{2}}}_{\text{Gini impurity}}. \end{align*}From the above and Cor. 3.2.2 we obtain the following corollary.
Corollary 3.3.2.
The minimizer of the Brier loss is the Bayes predictor \(f^{*}=p\), that is
\begin{align*} f^{*}_{k}(x) = p_{k}(x) = \P{Y=k\mid X}. \end{align*}A constant vector in \(\Delta_{K}\) has constant components \(c_k\). We can therefore use (3.2.2) with \(\1{Y=k}\) in the role of \(Y\). The optimal constant is \(\E{\1{Y=k}} = p_k\) and the variance is \(\V{\1{Y=k}} = p_k(1-p_k)\). Thus the best-in-class predictor and its risk are
\begin{align*} c^{*} &=p, & c_{k} &= \E{\1{Y=k}}, & R(c^{*})&=1-\sum_{k\in\Kset}p_k^2. \end{align*}Replacing the marginal probabilities by sample frequencies gives
\begin{align*} \hat c&=\hat p, & c_{k} &=\frac{|\Tset_{k}|}{|\Tset|}, & \hat R_{\Tset}(\hat c) &= 1 - \sum_{k\in\Kset} \hat p_{k}^{2}. \tag{3.3.7} \end{align*}Affine scores as predictors need a transformation to give valid probability predictions, since an unconstrained affine rule does stay in the simplex \(\Delta_K\). The sigmoid and softmax transformations form one way to achieve the required mapping:
\begin{align*} \sm: \R &\to (0,1), & \sm(z) &= \frac{1}{1+e^{-z}}, \tag{3.3.8} \\ \sm: \R^{k} &\to (0,1)^{k}, & \sm_{k}(s) &= \frac{e^{s_{k}}}{\sum_{j\in\Kset} e^{s_{j}}}, & k&=2, 3, 4, \ldots. \tag{3.3.9} \end{align*}Observe that for for binary classification, i.e., \(k=2\),
\begin{align*} \sigma_{0}(a,b) &= \frac{e^{a}}{e^{a}+e^{b}} = \frac{1}{1 + e^{b-a}}. \end{align*}Thus, for \(k=2\), we can write the softmax in terms of the sigmoid function,
\begin{align*} \sigma_{0}(a,b) = \sigma(b-a) = 1- \sigma(a-b) = 1-\sigma_{1}(a,b). \end{align*}Taking one intercept \(\beta_{0k}\) and one weight vector \(\beta_{k}\) per class, and writing \(\beta_{k}(x) = \beta_{0k} + \ip{\beta_{k}, x}\) for the affine score of class \(k\), write \(\beta(x)=(\beta_k(x))_{k\in\Kset}\) and let \(\theta\) collect these coefficients. The model class \(\Fset_{\mathrm{softmax}}=\{f_\theta\}\) consists of the rules
\begin{align*} f_{\theta}(x) &= \sm(\beta(x)) \in \Delta_K, & f_{\theta,k}(x) &= \sm_{k}(\beta(x)) = \PP{\theta}{Y=k\mid X=x}, \tag{3.3.10} \end{align*}where the rhs is the probabilityunder the model with coefficients \(\theta\).
This model has \(K(p+1)\) parameters: for each of the \(K\) classes one intercept \(\beta_{0}\) and \(p\) weights for the \(\beta_{k}\). Not all of them can be recovered from data, because an extra factor \(e^{c_{0} + \ip{c, x}}\) cancels between the numerator and the denominator of (3.3.10). Only \((K-1)(p+1)\) parameters are therefore necessary. For \(\Kset=\set{0,1}\), we write \(\beta(x)=\beta_1(x)-\beta_0(x)\) and obtain
\begin{align*} f_{\theta,0}(x)=1-\sigma(\beta(x)),\qquad f_{\theta,1}(x)=\sigma(\beta(x)). \end{align*}Under Brier loss, the training risk is
\begin{align*} \hat R_{\Tset}(f_\theta) =\frac{1}{|\Tset|}\sum_{(x,y)\in\Tset}\sum_{k\in\Kset} \rb{r_k(y)-f_{\theta,k}(x)}^2. \end{align*}Fitting means minimizing this expression over the coefficients \(\theta\). This cannot be solved algebra, we discuss the numerical optimization in Chapter 5.
3.3.3 Cross-entropy loss
The cross-entropy loss35Wikipedia: Cross-entropy. arises from the conditional likelihood of the labels. Assuming the labels are independent conditional on their feature vectors, and taking the negative logarithm, the average log-likelihood under a candidate rule \(f\) gives
\begin{align*} \frac{1}{|\Tset|}\log \prod_{(x,y)\in\Tset}\prod_{k\in\Kset} f_k(x)^{r_{k}(y)} = \frac{1}{|\Tset|}\sum_{(x,y)\in\Tset}\sum_{k\in\Kset} r_{k}(y)\log f_k(x) = - \frac{1}{|\Tset|}\sum_{(x,y)\in\Tset}\lscr(r(y), f(x)), \end{align*}where the cross-entropy loss is defined as
\begin{align*} \lscr(r(y),f(x)) &= -\sum_{k\in\Kset}r_k(y)\log f_k(x), & \lscr \in [0,\infty]. \tag{3.3.11} \end{align*}A numerical example shows that cross-entropy loss36Similar to Brier loss. assigns different losses to predictions with the same most likely class. For the example of the Brier loss, here
\begin{align*} \lscr(r(1),p^{A}) &= -\rb{0\cdot\log p^{A}_{0} + 1\cdot\log p^{A}_{1}} \approx 0.67, \\ \lscr(r(1),p^{B}) &= -\rb{0\cdot\log p^{B}_{0} + 1\cdot\log p^{B}_{1}} \approx 0.01. \end{align*}Observe also that as \(0\log 0=0\), a class with zero observed weight, i.e., \(r_k(y)=0\), contributes zero, and by taking \(\log 0 = -\infty\), assigning probability zero to the observed class, i.e., \(r_k(y)=1\), gives infinite loss.
For the Bayes predictor we minimize population risk over all prediction functions.
Theorem 3.3.3.
For every \(f:\Xset\to\Delta_K\),
\begin{equation*} \begin{split} R(f)&=\E{\lscr(r(Y), f(X))}\\ &= \sum_{k\in\Kset} \E{ p_{k}(X)\log \frac{p_{k}(X)}{f_{k}(X)}} - \sum_{k\in\Kset}\E{ p_{k}(X)\log p_{k}(X)}. \end{split} \tag{3.3.12} \end{equation*}Proof
Condition on \(X\). Then, as the \(k\)th component of \(r(Y)\) is \(\1{Y=k}\),
\begin{align*} \E{\lscr(r(Y), f(X)) \given X} &= \sum_{k\in\Kset} \E{\1{Y=k}\log\frac{1}{f_k(X)} \given X} \\ &= \sum_{k\in\Kset}p_k(X)\log\frac{1}{f_k(X)}. \end{align*}Adding and subtracting \(\sum_{k}p_k(X)\log p_k(X)\) gives
\begin{align*} \sum_{k\in\Kset}p_k(X)\log\frac{p_k(X)}{f_k(X)} -\sum_{k\in\Kset}p_k(X)\log p_k(X). \end{align*}Taking the expectation establishes the claim.
The first term of this decomposition of the risk is the relative entropy37Wikipedia: Kullback-Leibler divergence. between \(p(X)\) and \(f(X)\), and the second is the conditional entropy38Wikipedia: Conditional entropy. of \(Y\) given \(X\). The first is non-negative by Gibbs’ inequality39Wikipedia: Gibbs’ inequality. and zero exactly when \(f(X)=p(X)\)
Corollary 3.3.4.
The minimizer of \(\E{\lscr(r(Y),f(X))}\) in (3.1.4) is the Bayes classifier \(f^{*}=p\), that is \( f^{*}_{k}(x) = \P{Y=k\mid X=x}. \)
A constant vector as predictor has constant components \(c_k\). Substituting \(f_k(X)=c_k\) into the loss gives
\begin{align*} R(c) &= -\E{\sum_{k\in\Kset}r_k(Y)\log c_k} = -\sum_{k\in\Kset}\E{r_k(Y)}\log c_k &= -\sum_{k\in\Kset}p_k\log c_k \\ &= \sum_{k\in\Kset}p_k\log\frac{p_k}{c_k} -\sum_{k\in\Kset}p_k\log p_k, \end{align*}since \(\E{r_k(Y)}=\P{Y=k}=p_k\). The first term in the last line is the relative entropy between \(p\) and \(c\), so by Gibbs’ inequality it is non-negative and vanishes precisely at \(c=p\). The optimal constant predictors are the same as in the Brier analysis: \(c^*=p\) and \(\hat c=\hat p\), with the empirical predictor given by (3.3.7). The corresponding risks are now the population and empirical entropies:
\begin{align*} R(c^*)&=-\sum_{k\in\Kset}p_k\log p_k, & \hat R_{\Tset}(\hat c)&=-\sum_{k\in\Kset}\hat p_k\log\hat p_k. \end{align*}Affine scores as predictors use the same softmax model (3.3.10) as in the Brier analysis. Fitting this model with cross-entropy gives logistic regression. Fitting the coefficients requires numerical optimization, which we discuss in Chapter 5.
3.3.4 Absolute loss
The absolute loss
\begin{align*} \lscr(r(y),f(x)) &= \sum_{k\in\Kset}|r_k(y)-f_k(x)|, & \lscr \in [0,2], \end{align*}does not generally give the true class probabilities as its Bayes rule. Take \(\Kset=\set{0,1}\) and let \(f(x)=(1-u,u)\), with \(u\in[0,1]\). Here \(u\) is the predicted probability of class \(1\), while \(p_1(x)\) is its true conditional probability. Since \(r(0)=(1,0)\) and \(r(1)=(0,1)\), the two possible losses are
\begin{align*} \lscr(r(0),f(x)) &=|1-(1-u)|+|0-u|=2u,\\ \lscr(r(1),f(x)) &=|0-(1-u)|+|1-u|=2(1-u). \end{align*}Weighting these losses by the true class probabilities gives
\begin{align*} \E{\lscr(r(Y),f(X))\mid X} &=2p_0(X)u+2p_1(X)(1-u)\\ &=2p_1(X)+2u\rb{1-2p_1(X)}. \end{align*}This is linear in \(u\). If \(p_1(x)>1/2\), its coefficient of \(u\) is negative, so increasing \(u\) lowers the risk all the way to \(u=1\). If \(p_1(x)<1/2\), the coefficient is positive, so the minimum is at \(u=0\). If \(p_1(x)=1/2\), every \(u\in[0,1]\) gives the same risk.
Absolute loss can be used to learn class predictions, but its risk minimizer does not generally recover how plausible each class is. We prefer Brier loss and cross-entropy when we also want to learn these class probabilities.
3.4 Model flexibility
We have now studied losses and constant or affine rules for regression, nominal classification, and ordinal classification. We next return to regression under squared loss to examine two other ways of constructing a fitted rule. Both aim to approximate the conditional mean \(m(x)=\E{Y\given X=x}\), but they control flexibility differently. Nearest neighbors fit a constant locally; polynomial regression fits a function from a class whose degree we choose.
3.4.1 Nearest neighbors
If several training samples have exactly the feature vector \(x\), we can estimate \(m(x)\) by averaging their outcomes. For continuously distributed features, exact matches to a specified \(x\) generally do not occur. Instead, we can average outcomes at feature vectors near \(x\), using the idea that their conditional means should also be close.
Choose a number of neighbors \(k\), with \(1\leq k\leq n\), and measure closeness by Euclidean distance:
\begin{align*} \norm{x_i-x}_2 =\left(\sum_{j=1}^p (x_i(j)-x(j))^2\right)^{1/2}. \end{align*}Let \(i_1(x),\ldots,i_n(x)\) be the training indices ordered by increasing distance to \(x\). Break equal-distance ties by the original sample index, so that the first \(k\) indices always identify exactly \(k\) samples, including repeated samples when present. The \(k\)-nearest-neighbor (KNN)40We use lowercase \(k\) for the number of neighbors; uppercase \(K\) continues to denote the number of classes. prediction is
\begin{align*} \hat f_{k,\Tset}(x)=\frac{1}{k}\sum_{a=1}^k y_{i_a(x)}. \tag{3.4.1} \end{align*}This is precisely the fitted constant of (3.2.3), but fitted to the local list \(\Tset_k(x)=[(x_{i_1(x)},y_{i_1(x)}),\ldots,(x_{i_k(x)},y_{i_k(x)})]\). The list changes with the prediction point. The resulting rule can therefore follow a nonlinear conditional mean even though each individual prediction is obtained by fitting a constant.
\begin{algorithm}
\caption{Predict by averaging the outcomes of exactly \(k\) nearest training samples.}
\begin{algorithmic}[1]
\State \textbf{Input:} a training list $\Tset$, a feature vector $x$, and an integer $1\leq k\leq|\Tset|$.
\State \textbf{Output:} a numerical prediction at $x$.
\Procedure{KnnPredict}{$\Tset,x,k$}
    \State Order the indices $i_1,\ldots,i_n$ by increasing $\norm{x_i-x}_2$, breaking ties by index.
    \Return $\pr{Average}([y_{i_1},\ldots,y_{i_k}])$
\EndProcedure
\end{algorithmic}

\end{algorithm}
Distances depend on the units of the features. A coordinate measured in euros can dominate one measured in kilometers even if both are useful. One common choice is to center each feature and divide it by its training standard deviation before calculating distances. The same transformation, with the same fitted means and standard deviations, is then applied to new inputs. For \(1\leq j\leq p\), let41We apply the last transformation only when \(\sigma(j)>0\); constant features can be omitted.
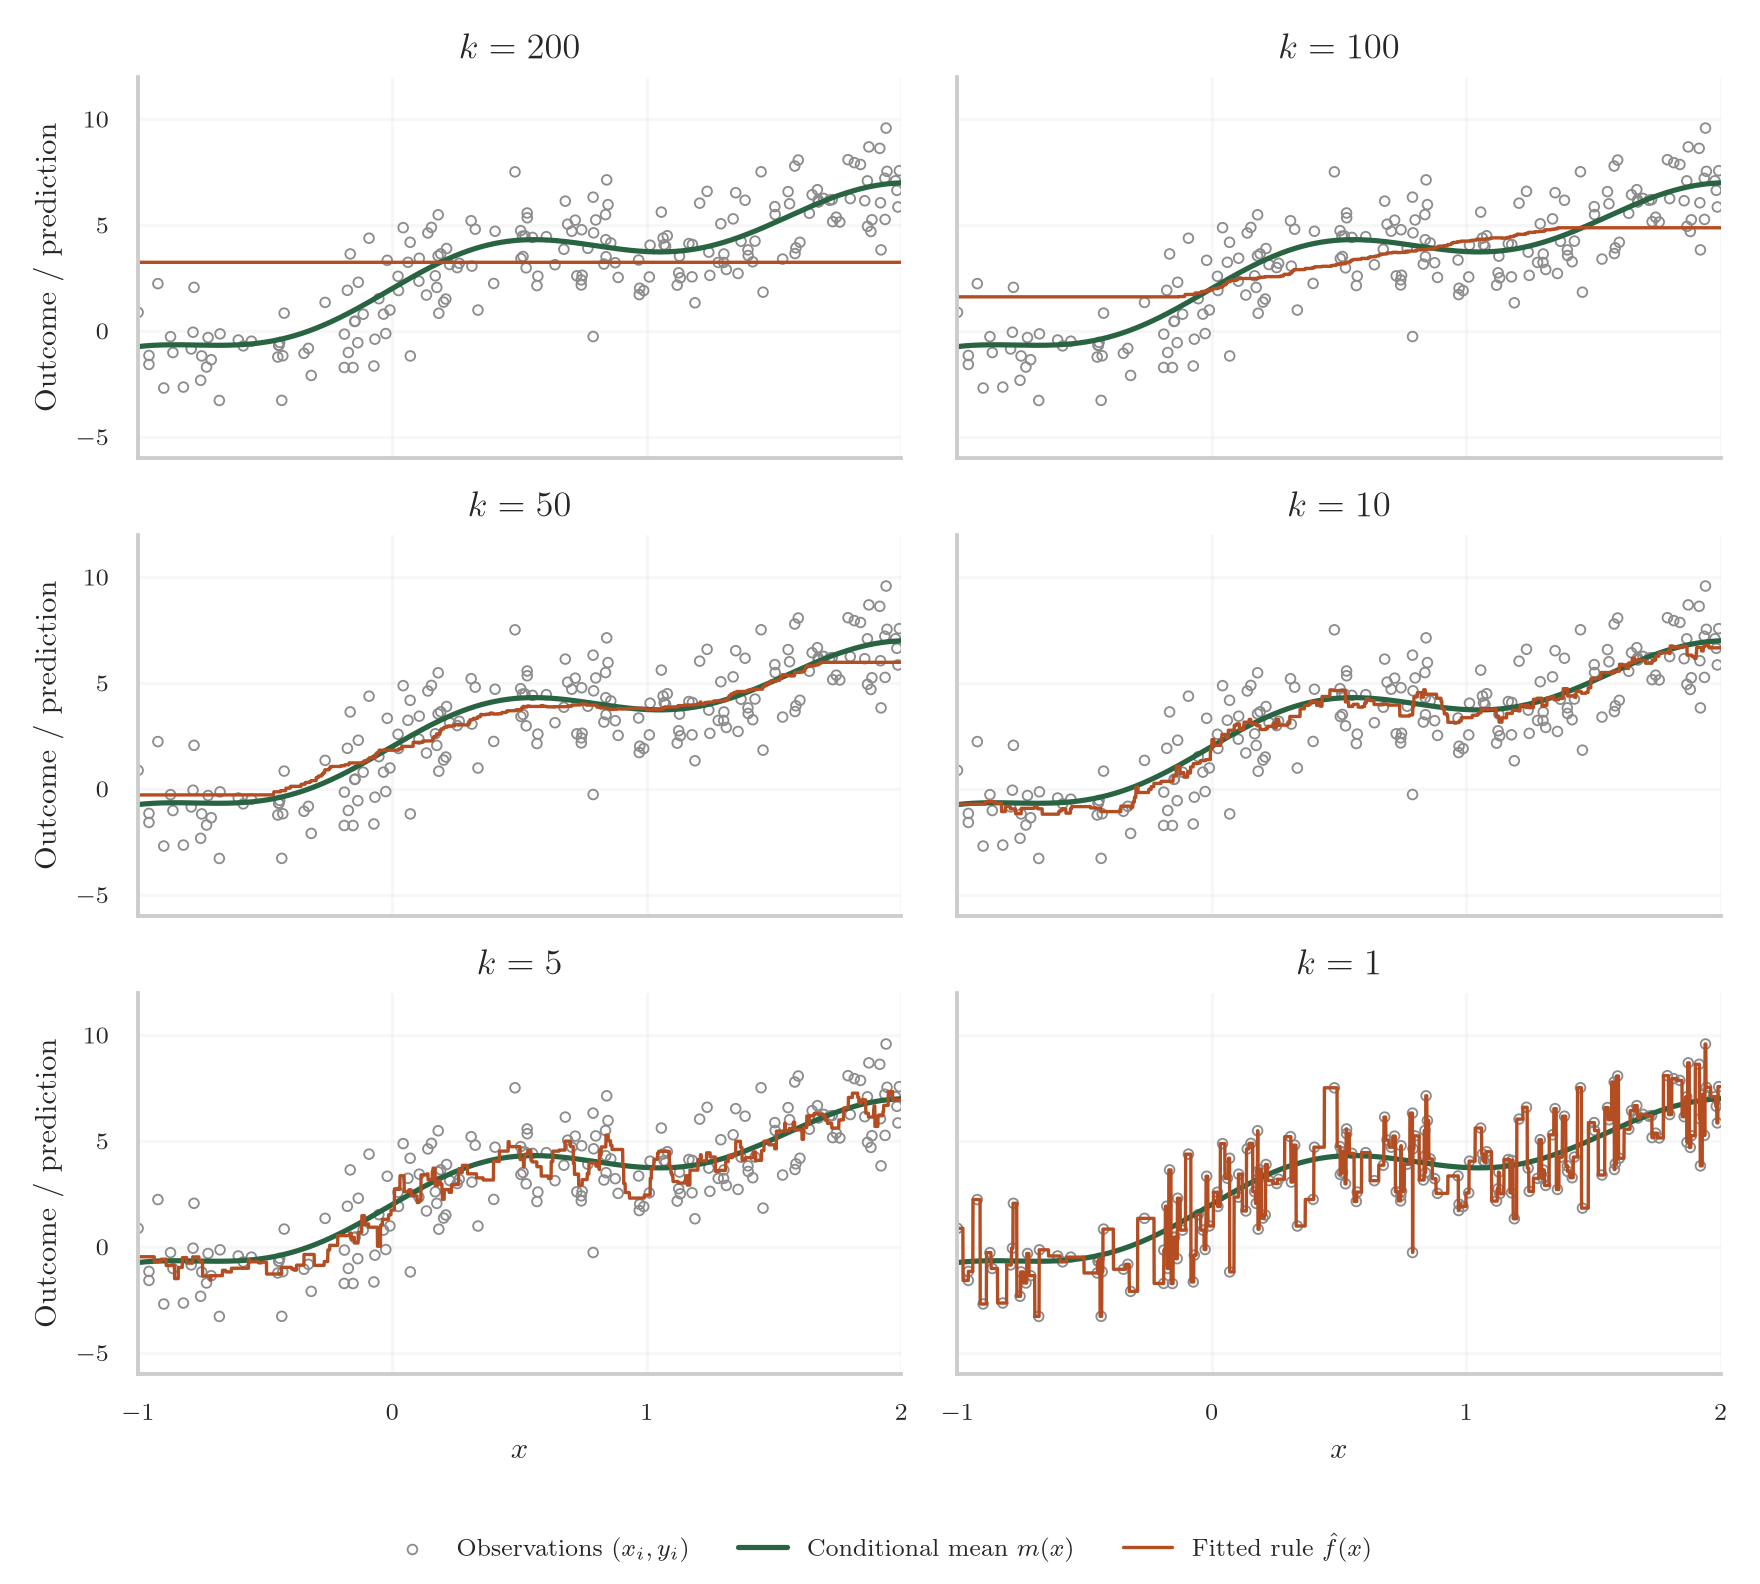
\begin{align*} \mu(j)&=\frac{1}{|\Tset|}\sum_{(x,y)\in\Tset}x(j),& \sigma(j)&=\sqrt{\frac{1}{|\Tset|}\sum_{(x,y)\in\Tset}(x(j)-\mu(j))^2},& \tilde x_i(j)&=\frac{x_i(j)-\mu(j)}{\sigma(j)}. \tag{3.4.2} \end{align*}A numerical example demonstrates clearly the effect of \(k\). Consider the conditional mean
\begin{align*} m(x)=2-\frac{1}{2}x^2+3x+\sin(4x),\qquad -1\leq x\leq2. \tag{3.4.3} \end{align*}Generate \(n=200\) independent samples according to
\begin{align*} X_i\sim\operatorname{Unif}(-1,2),\qquad Y_i=m(X_i)+\varepsilon_i,\qquad \varepsilon_i\sim\mathcal N(0,1.5^2), \end{align*}with the noises independent of the inputs and of one another. Then \(\E{Y_i\given X_i=x}=m(x)\).42Because this is a constructed example, we know \(m\); in an application we only observe the pairs \((x_i,y_i)\).
Fig. 3.5 compares \(k=200,100,50,10,5,1\) on the same sample. At \(k=200\) the rule is constant and cannot follow the trend or the oscillations. At \(k=1\), the fitted rule reproduces each training outcome, including its noise, which is clearly overfitting.
When the number of features \(p\) is large, e.g. \(p\geq 10\), the nearest neighbors of \(x\) are no longer close to \(x\). Two computations show this for samples that are uniformly distributed on \([0,1]^p\).
First, consider a sub-cube with sidelength43Hence with volume \(a^p\). \(a\) contains a fraction \(s\) of the samples. Then, \(a = s^{1/p}\). For \(s=0.01\) and \(p=10\) this side length is \(0.01^{1/10}\approx 0.63\): a neighborhood that holds 1% of the samples spans 63% of the range of each feature.
Second, let \(X\) and \(X'\) be independent uniform points in \([0,1]^p\). Then
\begin{align*} \E{\norm{X-X'}_2^2} &= \sum_{j=1}^{p}\E{(X(j)-X'(j))^2} = \frac{p}{6}, \tag{3.4.4} \\ \V{\norm{X-X'}_2^2} &= \sum_{j=1}^{p}\V{(X(j)-X'(j))^2} = \frac{7p}{180}, \tag{3.4.5} \end{align*}where the second line uses that the coordinate differences are independent. The squared coefficient of variation44The variance divided by the squared mean. is
\begin{align*} \frac{\V{\norm{X-X'}_2^2}}{\E{\norm{X-X'}_2^2}^{\,2}} = \frac{7}{5p}. \tag{3.4.6} \end{align*}Thus, as \(p\) grows, the variation of squared distances relative to their mean becomes small: all points lie roughly equally far away. The \(k\) nearest samples are then barely closer to \(x\) than the other samples, so their average says little more about \(m(x)\) than an average over arbitrary samples. Yet using all \(n\) observations is also undesirable, since it gives the global constant predictor.
This is the curse of dimensionality: local averaging becomes difficult in high dimension. An alternative restricts the rule to a class \(\Fset\) with a fixed number of parameters. All \(n\) samples then contribute to fitting each parameter, not only the \(k\) samples nearest to \(x\).
Polynomial regression is one such class. For a nonnegative integer degree \(q\), define
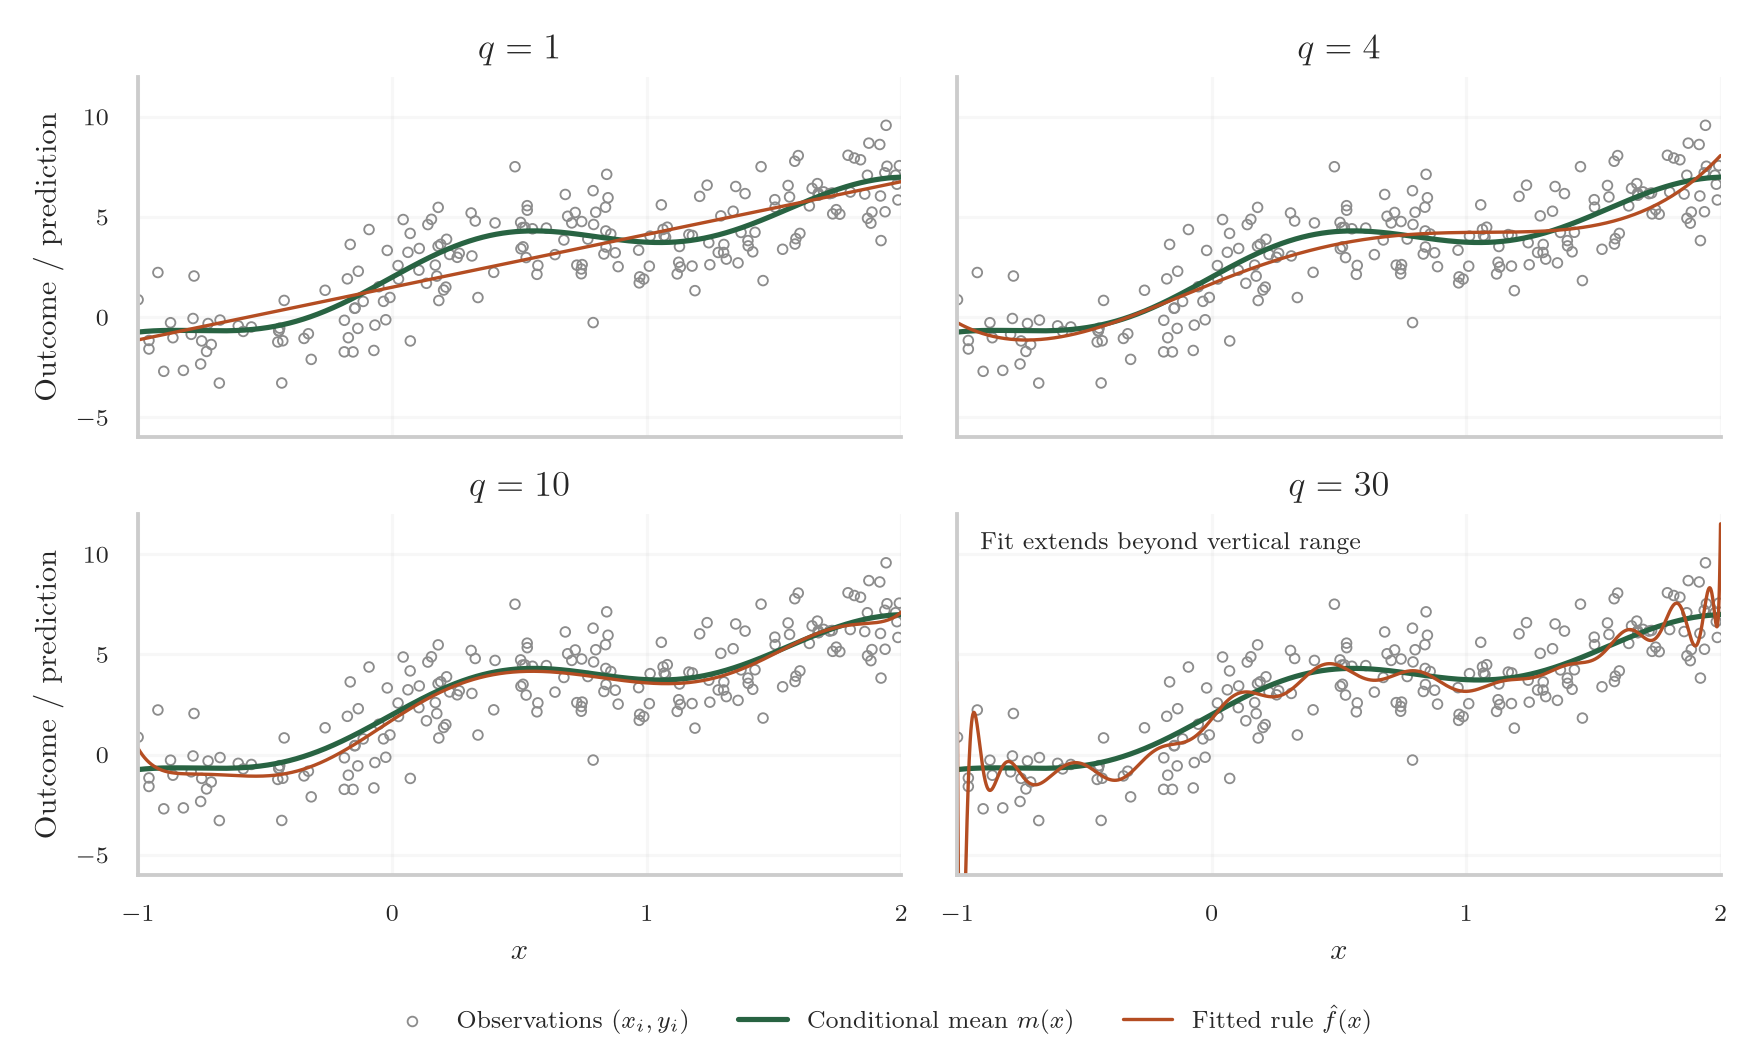
\begin{align*} \Fset_q =\left\{f_\beta:f_\beta(x)=\beta_0+\sum_{j=1}^q\beta_jx^j,\ \beta\in\R^{q+1}\right\}. \tag{3.4.7} \end{align*}The cases \(q=0\) and \(q=1\) recover the constant and affine classes for one numerical input. For \(q>1\), the rule is generally nonlinear in \(x\), but remains affine in the transformed features \((x,x^2,\ldots,x^q)\) and linear in the coefficients. Fitting therefore uses the same least-squares method as before:
\begin{align*} \hat\beta=\argmin_{\beta\in\R^{q+1}} \frac{1}{|\Tset|}\sum_{(x,y)\in\Tset} \left(y-\beta_0-\sum_{j=1}^q\beta_jx^j\right)^2. \end{align*}The coefficients \(\beta\) are parameters: least squares fits them for a given degree. The degree \(q\) is a hyperparameter: it fixes the class \(\Fset_q\) in which we fit.
Fig. 3.6 compares degrees \(q=1,4,10,30\) on the same observations used for KNN. An affine rule, \(q=1\), cannot follow the oscillations in \(m\). A polynomial of degree \(q\) has at most \(q-1\) turning points, so a higher degree can improve the approximation of \(m\), but it also lets the fit respond more strongly to the noise in the sample. The \(q=10\) fit follows \(m\) closely; the \(q=30\) fit adds oscillations, especially near the endpoints.
3.5 Regularization
Regularization addresses the problem that a method can be too flexible. When the training outcomes contain noise, a flexible method can adapt not only to stable patterns, but also to accidental variation in the training sample. One way is to restrict the fitted rule deliberately by making \(\Fset\) small; another way is to make complicated rules more expensive in the fitting problem.45Wikipedia: Regularization (mathematics).
Starting from the OLS problem (3.2.4), ridge regression46Wikipedia: Ridge regression. replaces the least-squares criterion by
\begin{align*} \min_{\beta_{0},\beta} \frac{1}{2|\Tset|}\sum_{(x,y)\in\Tset}(\beta(x)-y)^2 +\frac{\lambda}{2}\norm{\beta}_2^2, \qquad \norm{\beta}_2^2 = \sum_j \beta_j^2, \tag{3.5.1} \end{align*}where \(\lambda\geq0\) is a penalty parameter, or regularization parameter. A larger \(\lambda\) makes large coefficients more expensive. Lasso47Wikipedia: Lasso (statistics). uses the same idea, again starting from (3.2.4), but replaces the squared \(2\)-norm penalty by a \(1\)-norm penalty:
\begin{align*} \min_{\beta_{0},\beta} \frac{1}{2|\Tset|}\sum_{(x,y)\in\Tset}(\beta(x)-y)^2 +\lambda\norm{\beta}_1, \qquad \norm{\beta}_1 = \sum_j |\beta_j|. \end{align*}These penalties shrink the fitted coefficients and can reduce variance, at the cost of some bias—an instance of the bias-variance tradeoff. The two penalties differ in one important respect: the lasso can set coefficients exactly to zero, so it also performs variable selection in the sense of Section 3.2, while ridge regression only shrinks the coefficients.
Before adding a penalty term, we should standardize each feature using its training mean and standard deviation, as in (3.4.2).
Note that standardization is unnecessary for unregularized OLS: the fitted predictions are unchanged by rescaling a feature. Here, however, it is essential: rescaling changes the coefficient and therefore the penalty applied to it.
3.6 Validation and testing
Above we discussed several predictors and risks. We next discuss methods to assses the quality of the fitting process. First we establish that training risk is optimmistic about the real risk.
As the fitting procedure uses the sample outcomes \(y_i\), the predictor will typically score well on the training samples. Fix a model class \(\Fset\). Both \(\hat f_{\Fset}\) and \(f_{\Fset}^*\) belong to \(\Fset\): the former minimizes empirical risk \(\hat R_{\Tset}\), and the latter minimizes population risk \(R\). Averaging the training risks over the random training sample \(\Tset\), we obtain
\begin{align*} \E{\hat R_{\Tset}(\hat f_{\Fset})} \stackrel{1}{\leq} \E{\hat R_{\Tset}(f_{\Fset}^*)} \stackrel{2}{=}R(f_{\Fset}^*) \stackrel{3}{\leq} R(\hat f_{\Fset}). \end{align*}Step 1 holds because \(\hat f_{\Fset}\) minimizes empirical training risk over \(\Fset\) while \(f_{\Fset}^*\) minimizes the population risk over \(\Fset\). Step 2 holds because \(f_{\Fset}^*\) is a fixed population rule, so its empirical risk is unbiased. Step 3 holds because \(f_{\Fset}^*\) minimizes population risk over \(\Fset\), and \(\hat f_{\Fset}\) belongs to \(\Fset\) but does not necessarily minimize population risk Thus training risk is optimistic on average over training samples.
Training risk can therefore give an overly optimistic assessment of a fitted predictor. We need separate data to select and assess prediction rules. We next discuss how to use validation data for selection and test data to assess the final rule.
3.6.1 Training, validation, and test data
Choosing and assessing a prediction rule takes three steps. First, we select a function class \(\Fset\) over which we fit. A function in \(\Fset\) is specified by hyperparameters and parameters. For instance, for the union of the polynomial classes (3.4.7), the degree \(q\) is a hyperparameter and the coefficients \(\beta_0,\ldots,\beta_q\) are the parameters. Here we discuss how to tune the hyperparameters and the coeficients and assess how well the final result would do on a new observation \(X\). To tune a hyperparameter, we fix in advance a finite set of values to compare, for instance the degrees \(\Gamma = \set{0,1,\ldots,30}\). Each value in this set is a candidate, and the rule fitted at a candidate is a candidate rule.
For independent observations from a common population, we can randomly divide the available sample into three disjoint lists:
- The training list \(\Tset\): used to fit candidate rules.
- The validation list \(\Vset\): used to select a candidate.
- The test list \(\Eset\): kept aside to assess the final rule after selection and fitting are complete.
Splitting the samples into these subsets affects both fitting accuracy and evaluation precision: more training data can improve a fitted rule, while more evaluation data make its measured risk more precise. There is no single split proportion that is appropriate for every sample size and prediction problem.
Let \(\Gamma\) be a finite collection of candidate settings and let \(\hat f_{\gamma,\Tset}\) be the rule fitted with setting \(\gamma\). Now we use the validation set \(\Vset\) to find the best \(\gamma\). Writing the risk on the validation set as \(\hat R_\Vset(\hat f_{\gamma, \Tset})\),48Note: each candidate is fitted without using the validation observations. the best candidate is
\begin{align*} \hat\gamma=\argmin_{\gamma\in\Gamma} \hat R_{\Vset}(\hat f_{\gamma,\Tset}). \tag{3.6.1} \end{align*}After choosing \(\hat\gamma\), we can refit on the concatenated list \( \Dset=\Tset+\Vset. \) The final rule is then \(\hat f_{\hat\gamma,\Dset}\).
Finally, we use the test list to assess the final rule. Its test risk
\begin{align*} \hat R_{\Eset}(\hat f_{\hat\gamma,\Dset}) \end{align*}is the average loss of \(\hat f_{\hat\gamma,\Dset}\) over the test samples. The test samples are used neither to fit the parameters nor to select \(\hat\gamma\). For the final rule they are therefore new observations, and the test risk estimates its risk \(R(\hat f_{\hat\gamma,\Dset})\) on a new observation \((X,Y)\). Since the test risk is an average of losses on independent samples, a larger test list gives a more precise estimate.
Preprocessing is part of fitting. Means and standard deviations used to scale inputs must be estimated on the training part, then applied unchanged to the validation part. Feature selection, missing-value imputation, and other transformations estimated from data must follow the same procedure. Allowing the validation or test data to influence fitting is called data leakage.
3.6.2 Cross-validation
In the procedure above the candidate rules are fitted on \(\Tset\) only, and \(\Vset\) is never used for this purpose. Cross-validation divides \(\Dset=\Tset+\Vset\) instead into several parts. Each part serves once as validation list, while the rules are fitted on the other parts. Every sample in \(\Dset\) is then used for fitting and for validation, but never both in the same fit.
Let \(N=|\Dset|\), and divide its sample indices into \(F\) disjoint non-empty folds \(\Iset_1,\ldots,\Iset_F\), usually of nearly equal size. For fold \(b\), write
\begin{align*} \Dset_b &=[(x_i,y_i):i\in\Iset_b],& \Dset_{-b} &= \Dset\setminus \Dset_{b} = [(x_i,y_i):i\notin\Iset_b]. \end{align*}In \(F\)-fold cross-validation, we fit a candiate \(\gamma\) on \(\Dset_{-b}\) and we evaluate its risk on \(\Dset_b\).49Use the same folds for every candidate, so their errors are compared on the same validation observations. Writing \(\hat f_{\gamma,\Dset_{-b}}\) for such a fit, the cross-validation criterion for candidate \(\gamma\) is
\begin{align*} \mathrm{CV}(\gamma) &=\frac{1}{|\Dset|}\sum_{b=1}^F\sum_{(x,y)\in\Dset_b} \lscr(r(y),\hat f_{\gamma,\Dset_{-b}}(x)) \\ &=\sum_{b=1}^F\frac{|\Dset_b|}{|\Dset|} \hat R_{\Dset_b}(\hat f_{\gamma,\Dset_{-b}}). \tag{3.6.2} \end{align*}Every sample contributes one loss, from a rule fitted without that sample’s fold. The weights account for unequal fold sizes. Now select
\begin{align*} \hat\gamma=\argmin_{\gamma\in\Gamma}\mathrm{CV}(\gamma). \end{align*}Again, once \(\hat \gamma\) is computed, fit the model on \(\Dset\) for this candidate.
A special case is when \(F=N\); this is called leave-one-out cross-validation: each fit omits just one sample.
\begin{algorithm}
\caption{Select a setting by cross-validation and refit on all development data.}
\begin{algorithmic}[1]
\State \textbf{Input:} a development list $\Dset$, candidate settings $\Gamma$, and $2\leq F\leq|\Dset|$.
\State \textbf{Output:} a selected setting and the final fitted rule.
\Procedure{CrossValidate}{$\Dset,\Gamma,F$}
    \State Divide the indices of $\Dset$ into folds $\Iset_1,\ldots,\Iset_F$.
    \For{$\gamma\in\Gamma$}
        \State $\mathrm{CV}(\gamma)\gets0$
        \For{$b=1,\ldots,F$}
            \State Fit all preprocessing and the rule at $\gamma$ on $\Dset_{-b}$.
            \State $\mathrm{CV}(\gamma)\gets\mathrm{CV}(\gamma)+
            \dfrac{|\Dset_b|}{|\Dset|}\cdot\hat R_{\Dset_b}(\hat f_{\gamma,\Dset_{-b}})$
        \EndFor
    \EndFor
    \State $\hat\gamma\gets$ a minimizer of $\mathrm{CV}(\gamma)$ over $\Gamma$
    \State Refit preprocessing and the rule at $\hat\gamma$ on all of $\Dset$.
    \Return $(\hat\gamma,\hat f_{\hat\gamma,\Dset})$
\EndProcedure
\end{algorithmic}

\end{algorithm}
The number of folds \(F\) affects cross-validation in three ways.
First, with equal folds, each fold rule is fitted on \(N(1-1/F)\) samples, while the final rule \(\hat f_{\hat\gamma,\Dset}\) is fitted on all \(N\). A rule fitted on fewer samples has a larger estimation error, so with cross-validation we obtain usually less good predictors. Hence \(\mathrm{CV}(\gamma)\) tends to be somewhat larger than the risk of the rule fitted at \(\gamma\) on all of \(\Dset\).
Second, cross-validation fits every candidate \(F\) times, so \(F|\Gamma|\) fits in total, plus the final refit. Hence, CV increases the compuational load.
Third, the random variation of \(\mathrm{CV}(\gamma)\). Whatever \(F\), each sample of \(\Dset\) is validated exactly once, so \(\mathrm{CV}(\gamma)\) is always an average of \(N\) losses. What changes with \(F\) is how much the fold rules have in common. For large \(F\), any two fitting lists \(\Dset_{-b}\) share all but \(2N/F\) samples, so the fold rules are nearly the same rule. If that rule happens to be poor, all its losses are large together, and averaging them removes less of this chance variation than averaging over rules fitted on different samples. Taking \(F=5\) or \(F=10\) keeps the fold training size at 80 or 90 percent of \(N\), with 5 or 10 fits per candidate.
3.7 Assessing a classifier
Classification assessment addresses the problem that classification quality cannot always be summarized by the accuracy on a list \(\Sset\), the fraction of its label predictions that are correct,
\begin{align*} \text{accuracy} = \frac{1}{|\Sset|}\sum_{(x,y)\in \Sset}\1{d(f(x))=y}. \tag{3.7.1} \end{align*}In a two-class problem it is customary to call the class of special interest50This is often the rare class, such as a disease in a screening problem. positive and the other class negative. If only \(1\%\) of cases are positive, always predicting the negative class already gives \(99\%\) accuracy, but it misses every positive case. This is the problem of imbalanced data.
For two classes, the four possible outcomes of a prediction are collected in the confusion matrix: a true positive (TP) is a positive case predicted positive, a false positive (FP) is a negative case predicted positive, and true negatives (TN) and false negatives (FN) are defined analogously.
A screening example makes the terminology concrete. In breast-cancer screening, call the screening result positive when the X-ray is suspicious, and negative otherwise. After follow-up, we can compare this screening result with whether cancer was actually present. A true positive is a suspicious X-ray for a woman who has breast cancer; a false positive is a suspicious X-ray where no cancer is found; a false negative is a non-suspicious X-ray for a woman who does have breast cancer; and a true negative is a non-suspicious X-ray where no cancer is found.
In this example, recall is the fraction of women with breast cancer whose X-rays are flagged as suspicious. A test with high recall misses few cancer cases. Precision is the fraction of suspicious X-rays for which breast cancer is actually present. A test with high precision gives few false alarms among the women sent for further tests. The false-positive rate is the fraction of women without breast cancer whose X-rays are nevertheless flagged as suspicious.
A good screening test should have high recall, because missed cancer cases are serious. High precision is also desirable, but it can be hard to achieve when the disease is rare. In practice there is often a tradeoff: flagging more X-rays as suspicious can increase recall, but it may also create more false positives and lower precision.
Counting these outcomes over the evaluation set gives three useful rates. The true-positive rate, or recall,51The name comes from information retrieval: recall measures what fraction of all relevant cases the method retrieves, or ``recalls’’. Here the relevant cases are the positive cases. \(\mathrm{TP}/(\mathrm{TP}+\mathrm{FN})\), is the fraction of positive cases that are found. The false-positive rate, \(\mathrm{FP}/(\mathrm{FP}+\mathrm{TN})\), is the fraction of negative cases that are wrongly flagged. Precision, \(\mathrm{TP}/(\mathrm{TP}+\mathrm{FP})\), is the fraction of predicted positives that are correct. In the example above, always predicting the negative class has recall \(0\): none of the positive cases are found. The accuracy is high only because positive cases are rare.
The always-negative rule is an example of a baseline: a simple reference method, such as always predicting the most frequent class in classification, or the training mean in regression. Reporting the performance of a fitted method alongside a baseline shows whether it improves on this simple reference under the chosen evaluation measure.
3.8 Exercises
Conceptual 1.
The setup of supervised prediction uses three sets, the feature space \(\Xset\), the outcome space \(\Yset\), and the prediction set \(\Aset\), and four functions, the prediction function \(f\), the decision map \(d\), the label-lifting map \(r\), and the loss function \(\lscr\). a. For each set, say what it contains and why we introduce it as a separate set. Why is it not enough to take \(\Aset=\Yset\)? b. For each function, give its domain and codomain, and explain its role. c. Why do we require \(d(r(y))=y\)? d. Work out all seven objects for classification with \(K\) classes, where the rule outputs class probabilities and the loss is the Brier loss e. Do the same for regression under squared loss.
Solution
Did you actually try? Write your solution down first for comparison.
Show the solution
We address the parts in order. a. \(\Xset\) contains the feature vectors: the information available about a case when we must predict. \(\Yset\) contains the outcomes as they are observed and reported, such as a number or a class label. \(\Aset\) contains the objects the rule may output. If \(\Aset=\Yset\), a classifier can only output a single label. A probability vector in \(\Delta_K\) also states how sure the rule is, and a label cannot carry that. A separate \(\Aset\) allows such outputs. b. \(f:\Xset\to\Aset\) is the rule we fit: it maps the features of a case to a prediction. \(d:\Aset\to\Yset\) converts a prediction into the value \(d(f(x))\) that we report. \(r:\Yset\to\Aset\) puts an observed outcome into the prediction set, so that it can be compared with \(f(x)\). \(\lscr:\Aset\times\Aset\to\R_+\) assigns the cost \(\lscr(r(y),f(x))\); it states which errors the application considers expensive. Since \(\lscr\) takes two elements of \(\Aset\), we need \(r\) before we can evaluate it. c. Suppose the rule predicts the lifted outcome exactly, \(f(x)=r(y)\). Then the reported value is \(d(f(x))=d(r(y))\), and the requirement ensures this equals \(y\). The reverse identity \(r(d(a))=a\) fails in general: after \(d\) has turned a probability vector into a label, the probabilities cannot be recovered. d. Classification: for numerical feature vectors, take \(\Xset\subseteq\R^p\). Then \(\Yset=\Kset=\set{1,\ldots,K}\), \(\Aset=\Delta_K\), and \(f:\Xset\to\Delta_K\) returns the predicted class-probability vector \(f(x)\). The decision map is \(d(f(x))=\argmax_k f_k(x)\), \(r_k(y)=\1{y=k}\), and \(\lscr(r(y),f(x))=\sum_{k\in\Kset}(r_k(y)-f_k(x))^2\). Indeed \(d(r(y))=y\), since the one-hot vector \(r(y)\) has its only nonzero component at \(k=y\). e. Regression: for numerical feature vectors, take \(\Xset\subseteq\R^p\). Then \(\Yset=\Aset=\R\), and \(f:\Xset\to\R\) returns a numerical prediction \(f(x)\). The maps \(d\) and \(r\) are the identity, and \(\lscr(y,f(x))=(y-f(x))^2/2\). In regression the distinction between \(\Yset\) and \(\Aset\) is not visible; it is needed when the rule outputs a different kind of object than the outcome.
Conceptual 2.
Consider the problem \(\argmin_f \hat R_{\Tset}(f)\), where \(f\) ranges over all functions \(\Xset\to\Aset\). Assume that \(\lscr(a,b)=0\) if and only if \(a=b\). a. Suppose the inputs \(x_1,\ldots,x_n\) are distinct. Describe all minimizers. How much computation does it take to find one? b. Now suppose several samples share the same input \(x\) but have different outcomes. What do the minimizers look like under squared loss? c. Let \(X\) have a continuous distribution. What does a minimizer predict for a new case, and what does its training risk tell us about its population risk? d. How does restricting \(f\) to a model class \(\Fset\) change these answers?
Solution
Did you actually try? Write your solution down first for comparison.
Show the solution
We address the parts in order. a. Since \(\lscr\geq0\), the training risk is at least \(0\). Every \(f\) with \(f(x_i)=r(y_i)\) for \(i=1,\ldots,n\) attains \(0\), so it is a minimizer. The values of \(f\) at all other points of \(\Xset\) do not enter \(\hat R_{\Tset}\), so they can be chosen freely: there are infinitely many minimizers. Finding one takes no computation beyond storing the training set. b. The training risk splits into one sum per distinct input. For each distinct input \(x\), the value \(f(x)\) minimizes the loss summed over the samples with that input. Under squared loss, this is the average of their outcomes. Values of \(f\) at other points remain free. c. With a continuous distribution, \(\P{X\in\set{x_1,\ldots,x_n}}=0\). A new case therefore almost surely has an input outside the training set, where the minimizer’s value was chosen freely. Equal, zero training risks do not imply equal or small population risks. d. In a model class, the value at one input constrains the values at others. For example, an affine rule \(\beta(x)=\beta_0+\ip{\beta,x}\) is fixed on all of \(\Xset\) by \(p+1\) coefficients. Fitting these coefficients to the training samples then also determines the predictions for new inputs. With \(n>p+1\) samples, an affine rule cannot in general pass through every training point, so fitting it generally requires trading off the losses at different samples.
Conceptual 3.
State the definitions of the concepts Bayes predictor, best-in-class predictor, and empirical-risk minimizer and use these definitions to explain the difference between them.
Solution
Did you actually try? Write your solution down first for comparison.
Show the solution
The three predictors differ along two axes: which risk is minimized, population risk \(R\) or training risk \(\hat R_{\Tset}\), and over which set of functions the minimization ranges, all prediction functions or the model class \(\Fset\).
- The Bayes predictor \(f^{*}=\argmin_{f} R(f)\), (3.1.4), minimizes population risk over all prediction functions.
- The best-in-class predictor \(f_{\Fset}^{*}=\argmin_{f\in\Fset} R(f)\), (3.1.5), also minimizes population risk, but only over \(\Fset\).
- The empirical risk minimizer \(\hat f_{\Fset}=\argmin_{f\in\Fset} \hat R_{\Tset}(f)\), (3.1.5), replaces population risk by training risk, still restricted to \(\Fset\).
Because \(\Fset\) is only one set of candidate functions among all possible ones, \(R(f_{\Fset}^{*})\ge R(f^{*})\).
Conceptual 4.
Suppose \(\Fset_1\subseteq\Fset_2\). What can be said about their training risk and their population risk after empirical-risk minimization?
Solution
Did you actually try? Write your solution down first for comparison.
Show the solution
Write \(\hat f_{\Fset_i}=\argmin_{f\in\Fset_i}\hat R_{\Tset}(f)\) for the empirical risk minimizer over \(\Fset_i\), \(i=1,2\), (3.1.5). The training risk cannot increase:
\begin{align*} \hat R_{\Tset}(\hat f_{\Fset_2}) \leq \hat R_{\Tset}(\hat f_{\Fset_1}), \end{align*}because the larger class contains all candidates in the smaller class. The population risk can nevertheless increase, because the larger class can fit random details of the training set and overfit.
Conceptual 5.
Classification could be fit directly under the zero-one loss (3.3.3), yet the Brier loss (3.3.6) (or cross-entropy) is used during training instead. a. Take \(\Kset=\set{0,1}\) and \(y=1\), so \(r(1)=(0,1)\). Compute the zero-one loss and the Brier loss of \(p^{A}=(0.49,0.51)\) and \(p^{B}=(0.01,0.99)\). Compare the two pairs of results. b. Both losses lead to the same rule for turning a prediction \(f(x)\) into a class label. Which map does this, and does it depend on the loss used during training? c. Why might we also report accuracy or misclassification rate when the classifier was fitted using Brier loss?
Solution
Did you actually try? Write your solution down first for comparison.
Show the solution
We address the parts in order. a. Under zero-one loss both \(p^{A}\) and \(p^{B}\) predict class \(1\), matching \(y=1\), so both receive loss \(0\); zero-one loss cannot separate them. Under Brier loss, \(\lscr(r(1),p^{A})\approx0.48\) while \(\lscr(r(1),p^{B})=0.0002\): it rewards \(p^{B}\) for lying much closer to the one-hot vector, even though both predictions give the same label. b. The decision map \(d(f(x))=\argmax_{k}f_k(x)\), (3.3.1), turns any prediction into a label; it is the same map whether \(f\) was fit under Brier loss, cross-entropy, or, in principle, zero-one loss. Only the objective used during fitting differs; the reported label is always read off by \(\argmax\). c. Accuracy and misclassification rate describe how often the reported class label is correct or incorrect, which is easy to interpret. Brier loss also assesses the predicted probabilities. These measures answer different questions, so reporting classification accuracy can complement evaluation under Brier loss.
Conceptual 6.
Take \(\Kset=\set{0,1}\) and an observed class \(y=1\). a. Compute the cross-entropy loss for \(p^{A}=(0,1)\) and \(p^{B}=(1,0)\). b. Why does assigning probability zero to the unobserved class cause no problem, while assigning probability zero to the observed class gives infinite loss?
Solution
Did you actually try? Write your solution down first for comparison.
Show the solution
We address the parts in order. a. The loss is \(-\log p_1\), so the two losses are \(0\) and \(+\infty\). b. The unobserved class has \(r_0(1)=0\) and contributes zero under the convention \(0\log0=0\). The observed class has \(r_1(1)=1\).
Conceptual 7.
One in a thousand screened patients carries a certain disease. Consider the predictor that declares every patient healthy. a. Compute its accuracy, (3.7.1). b. Compute its recall and its false-positive rate. c. Why does the accuracy from part a not reveal that this predictor is useless for screening?
Solution
Did you actually try? Write your solution down first for comparison.
Show the solution
We address the parts in order. a. The predictor is correct on the \(999\) healthy patients out of every \(1000\), so its accuracy is \(0.999\). b. It flags no patient as positive, so it finds none of the sick patients: recall \(\mathrm{TP}/(\mathrm{TP}+\mathrm{FN})=0/1=0\). It also raises no false alarms among the healthy patients, so its false-positive rate \(\mathrm{FP}/(\mathrm{FP}+\mathrm{TN})=0/999=0\). c. Accuracy averages correctness over all patients, and healthy patients vastly outnumber sick ones, so the \(999\) correct predictions on healthy patients swamp the complete failure on the single sick patient. Recall looks only at the sick patients and immediately exposes the failure, because it is \(0\) even though accuracy is \(0.999\).
Conceptual 8.
Consider \(10{,}000\) patients, of whom \(10\) have the disease. A predictor flags \(5\) patients as diseased, of whom \(1\) truly has the disease. a. Compute this predictor’s precision. b. Why is precision alone not enough to judge whether this predictor is useful for screening? c. What is a reasonable baseline to compare this predictor against here, and what would that baseline achieve on accuracy, recall, and precision?
Solution
Did you actually try? Write your solution down first for comparison.
Show the solution
We address the parts in order. a. Precision is \(\mathrm{TP}/(\mathrm{TP}+\mathrm{FP})=1/5=0.2\). b. Precision describes only the flagged patients. Here, the predictor finds just \(1\) of the \(10\) sick patients, so its recall is \(1/10=0.1\): it misses the other \(9\). Precision must therefore be considered together with recall. c. The always-negative rule (declaring every patient healthy) is a natural baseline here, since it always predicts the most frequent class. It reaches accuracy \(0.999\) and recall \(0\), and its precision is undefined, since \(\mathrm{TP}+\mathrm{FP}=0\). Comparing against it shows that the new predictor does find sick patients that the baseline misses entirely, even though its precision of \(0.2\) means \(4\) out of every \(5\) flagged patients undergo follow-up testing unnecessarily.
Conceptual 9.
a. What is the validation list \(\Vset\) used for? b. What is the test list \(\Eset\) used for? c. What is lost if \(\Vset\) and \(\Eset\) overlap, or if \(\Eset\) is used to choose between candidate rules? d. Should we fit the final rule on \(\Dset=\Tset+\Vset\) before testing it on \(\Eset\)? Explain why or why not.
Solution
Did you actually try? Write your solution down first for comparison.
Show the solution
We address the parts in order. a. The validation list is used to select among candidate rules fitted with different hyperparameter settings, (3.6.1). b. The test list is used once, at the very end, to estimate how the chosen rule performs on new data. c. If \(\Vset\) and \(\Eset\) overlap, or if \(\Eset\) is used to choose a candidate, this is data leakage: the test risk is no longer an unbiased estimate of performance on new data, because the chosen rule may have been selected for doing well on data that were supposed to be held out. d. Yes, usually. After selecting \(\hat\gamma\) using \(\Vset\), refitting on \(\Dset=\Tset+\Vset\) lets the final rule learn from more data. The test list \(\Eset\) must remain untouched until this final evaluation.
Conceptual 10.
kNN regression predicts by averaging the outcomes of the \(k\) training points closest to \(x\). Suppose the training inputs and a new input \(X\) are independent and uniformly distributed on \([0,1]^p\). Keep the training sample size \(n\) and the number of neighbors \(k\) fixed as \(p\) grows. Write \(x\) for the observed value of \(X\). a. What happens to the distance between \(x\) and its nearest neighbors as \(p\) grows? Explain your answer heuristically. b. Why does this make the kNN prediction less useful in high dimension? Explain your answer heuristically.
Solution
Did you actually try? Write your solution down first for comparison.
Show the solution
We address the parts in order. a. As \(p\) grows, distances increase and become concentrated relative to their mean. With a fixed number of training samples, the nearest neighbors are therefore barely closer than the other samples. b. Since the \(k\) nearest points are no longer meaningfully closer to \(x\) than the rest of the sample, averaging their outcomes says little more about \(m(x)\) than averaging over arbitrary points; the local-averaging idea behind kNN breaks down. This is the curse of dimensionality.
Conceptual 11.
In the cross-validation algorithm presented in this chapter, why must the candidate set \(\Gamma\) be finite?
Solution
Did you actually try? Write your solution down first for comparison.
Show the solution
The algorithm fits and evaluates a rule for every candidate \(\gamma\in\Gamma\). To complete this exhaustive search, \(\Gamma\) must therefore be finite.
Algorithmical 12.
What should replace ??? in the code below? Give code (pseudocode, Python, or R) or a precise conceptual description.
\begin{algorithm}
\begin{algorithmic}[1]
\State \textbf{Input:} conditional probabilities $p(x)$, predicted probabilities $f(x)$
\State \textbf{Output:} the relative-entropy and conditional-entropy terms at $x$
\Procedure{CrossEntropyDecomposition}{$x,p,f$}
    \State $\var{relative\_entropy} \gets$ ???
    \State $\var{conditional\_entropy} \gets -\sum_{k=1}^{K} p_{k}(x)\cdot\log p_{k}(x)$
    \Return $\var{relative\_entropy}, \var{conditional\_entropy}$
\EndProcedure
\end{algorithmic}

\end{algorithm}
Solution
Did you actually try? Write your solution down first for comparison.
Show the solution
as in (3.3.12).
Algorithmical 13.
What should replace ??? in the code below? Give code (pseudocode, Python, or R) or a precise conceptual description.
\begin{algorithm}
\begin{algorithmic}[1]
\State \textbf{Input:} a training list $\Tset$, a feature vector $x$, and an integer $1\leq k\leq|\Tset|$.
\State \textbf{Output:} a numerical prediction at $x$.
\Procedure{KnnPredict}{$\Tset,x,k$}
    \State Order the indices $i_1,\ldots,i_n$ by increasing $\norm{x_i-x}_2$, breaking ties by index.
    \Return ???
\EndProcedure
\end{algorithmic}

\end{algorithm}
Solution
Did you actually try? Write your solution down first for comparison.
Show the solution
The complete algorithm is in the main text.
Algorithmical 14.
Describe in your own words, or in pseudocode if you prefer, how \(F\)-fold cross-validation selects a candidate setting \(\gamma \in \Gamma\) and produces the final fitted rule.
Solution
Did you actually try? Write your solution down first for comparison.
Show the solution
Divide the development list \(\Dset=\Tset+\Vset\) into \(F\) roughly equal folds. For each candidate \(\gamma\in\Gamma\) and each fold \(b\), fit the rule at \(\gamma\) on all other folds, \(\Dset_{-b}\), and evaluate its risk on the held-out fold \(\Dset_b\); averaging the held-out losses over all observations gives the cross-validation criterion \(\mathrm{CV}(\gamma)\). Select \(\hat\gamma\) minimizing \(\mathrm{CV}(\gamma)\) over \(\Gamma\), then refit the rule at \(\hat\gamma\) on all of \(\Dset\) to obtain the final rule \(\hat f_{\hat\gamma,\Dset}\).
Technical 15.
Assume \(\E{Y^2}<\infty\), and let \(m(x)=\E{Y\mid X=x}\). Use the identity
\begin{align*} R(f)=\frac{1}{2}\E{(Y-f(X))^2} =\frac{1}{2}\E{\V{Y\mid X}}+\frac{1}{2}\E{(f(X)-m(X))^2} \end{align*}to derive the Bayes predictor and the Bayes risk. Also express the excess risk of an arbitrary predictor \(f\).
Solution
Did you actually try? Write your solution down first for comparison.
Show the solution
The decomposition is minimized when \(f(X)=m(X)\). Hence
\begin{align*} f^*(x)=m(x)=\E{Y\mid X=x},\qquad R(f^*)=\frac{1}{2}\E{\V{Y\mid X}}, \end{align*}and
\begin{align*} R(f)-R(f^*)=\frac{1}{2}\E{(f(X)-m(X))^2}. \end{align*}Technical 16.
Under squared loss, derive the optimal constant predictor \(c^*\) and its population risk.
Solution
Did you actually try? Write your solution down first for comparison.
Show the solution
Minimizing \(\E{(Y-c)^2}\) gives
\begin{align*} c^*=\E Y,\qquad R(c^*)=\frac{1}{2}\V Y. \end{align*}Technical 17.
Under squared loss, why is the minimum population risk over constant predictors equal to \(\frac{1}{2}\V Y\)?
Solution
Did you actually try? Write your solution down first for comparison.
Show the solution
By (3.2.2), the optimal constant predictor is \(c^*=\E Y\), with risk
\begin{align*} R(c^*)=\frac{1}{2}\E{\V{Y\mid X}}+\frac{1}{2}\E{m(X)^2}-\frac{1}{2}(\E Y)^2, \end{align*}from expanding \(\E{(m(X)-c)^2}\) at \(c=\E Y\). By Eve’s law (\(\V Y=\E{\V{Y\mid X}}+\V{\E{Y\mid X}}\)), the last two terms combine to \(\V{\E{Y\mid X}}\), giving \(R(c^*)=\frac{1}{2}\E{\V{Y\mid X}}+\frac{1}{2}\V{\E{Y\mid X}}=\frac{1}{2}\V Y\).
Technical 18.
Derive the approximation–estimation decomposition of the excess risk \(R(\hat f_{\Fset})-R(f^*)\). Explain why “approximation error” and “estimation error” are appropriate names.
Solution
Did you actually try? Write your solution down first for comparison.
Show the solution
Add and subtract \(R(f^*_{\Fset})\):
\begin{align*} R(\hat f_{\Fset})-R(f^*) = \underbrace{R(f^*_{\Fset})-R(f^*)}_{\text{approximation error}} +\underbrace{R(\hat f_{\Fset})-R(f^*_{\Fset})}_{\text{estimation error}}. \end{align*}\(R(f^*_{\Fset})-R(f^*)\) is the increase in risk caused by restricting the search to \(\Fset\): even the best rule in the class need not approximate the Bayes predictor \(f^*\) well, so it is the approximation error. \(R(\hat f_{\Fset})-R(f^*_{\Fset})\) arises only because \(\hat f_{\Fset}\) optimizes the training risk \(\hat R_{\Tset}\), estimated from the finite sample \(\Tset\), instead of the population risk \(R\); it is the estimation error of using the samples in \(\Tset\) in place of \(F_{X,Y}\).
Technical 19.
Derive the bias–variance decomposition for squared loss using the average prediction \(\bar f(x)=\EE{\Tset}{\hat f_{\Fset}(x)}\).
Solution
Did you actually try? Write your solution down first for comparison.
Show the solution
The derivation is given in the proof of Th. 3.2.3.
Technical 20.
For binary classification with \(\Kset=\set{0,1}\), consider the softmax predictor with affine scores \(\beta_0(x)\) and \(\beta_1(x)\). Set \(\beta(x)=\beta_1(x)-\beta_0(x)\). Show that the predicted probability of class \(1\) is \(\sigma(\beta(x))\), where \(\sigma(z)=(1+e^{-z})^{-1}\), and that the predicted probability of class \(0\) is \(1-\sigma(\beta(x))\). Why is \(\beta(x)\) again affine?
Solution
Did you actually try? Write your solution down first for comparison.
Show the solution
Divide the numerator and denominator of the class-\(1\) probability by \(e^{\beta_1(x)}\):
\begin{align*} \frac{e^{\beta_1(x)}}{e^{\beta_0(x)}+e^{\beta_1(x)}} &=\frac{1}{e^{\beta_0(x)-\beta_1(x)}+1} =\frac{1}{1+e^{-\beta(x)}} =\sigma(\beta(x)). \end{align*}The two probabilities sum to one, so the probability of class \(0\) is \(1-\sigma(\beta(x))\). Moreover,
\begin{align*} \beta(x) &=(\beta_{01}-\beta_{00})+\ip{\beta_1-\beta_0,x}, \end{align*}which is affine because it is the difference of two affine scores.
Technical 21.
For binary classification with \(\Kset=\set{0,1}\) and Brier loss, derive the Bayes predictor and explain what quantity it predicts.
Solution
Did you actually try? Write your solution down first for comparison.
Show the solution
For each \(k\in\{0,1\}\), the \(k\)th coordinate of \(r(Y)\) is the indicator \(\1{Y=k}\). Conditional on \(X=x\), this is Bernoulli with success probability \(p_k(x)=\P{Y=k\mid X=x}\). Thus, for a candidate predictor \(f(x)\in\Delta_2\), the conditional expected Brier loss is \[ \E{\lscr(r(Y),f(x))\mid X=x} =\sum_{k=0}^{1}\left[p_k(x)(1-p_k(x))+(p_k(x)-f_k(x))^2\right]. \] The first term for each class does not depend on \(f(x)\). The squared terms are minimized by setting \(f_k(x)=p_k(x)\). Since \(p(x)\in\Delta_2\), the Bayes predictor is
\begin{align*} f^*(x)=p(x),\qquad p_k(x)=\Pr(Y=k\mid X=x), \end{align*}which predicts the conditional probabilities of the two classes given the feature vector \(x\).